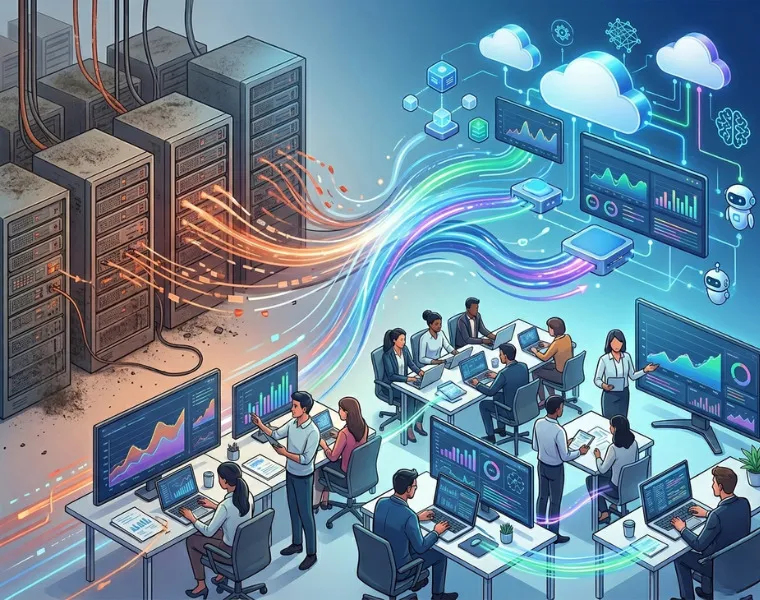


Traditional data warehouses and legacy monolithic systems were designed for an era when data moved slowly and lived entirely on local servers. Today, enterprise data does not stay in one place. It streams continuously from customer touchpoints, SaaS operational tools, payment processors, mobile applications, and web event trackers.
When legacy architectures encounter high data variety and real-time velocity, they break down. Engineering teams get stuck manually fixing broken nightly ETL scripts, while executive leadership waits days for basic operational reports.
The Modern Data Stack (MDS) solves this bottleneck. Built entirely as a modular, cloud-native ecosystem, it separates storage from compute, automates extraction, and simplifies data transformation. Here is how modern data stack architecture works, why it matters, and how forward-thinking companies implement it.
The Shift from Legacy ETL to Scalable Cloud ELT
The defining architectural shift of the modern data stack is moving from ETL (Extract, Transform, Load) to ELT (Extract, Load, Transform).
In traditional setups, raw records had to be cleaned and formatted before loading into a database. Any schema change upstream caused pipeline failure, forcing data engineers to diagnose code and rebuild tables from scratch.
Modern cloud architectures eliminate this fragility:
- Immediate ingestion: Connectors extract raw data from hundreds of sources and load it straight into cloud storage repositories without pre-processing delays.
- Decoupled storage and compute: Cloud warehouses dynamically scale compute power independently of storage volume, running heavy SQL transformations inside the warehouse in seconds.
- Preserved raw records: Because untouched original files are permanently stored, engineering teams can adjust business logic or test new data models retrospectively without having to re-fetch historical data from production APIs.
The 5 Essential Layers of Modern Data Architecture
A modern data stack discards bloated, single-vendor platforms in favor of best-of-breed modular tools connected through automated interfaces. The infrastructure is composed of five core functional tiers:
- Data Ingestion and Pipeline Automation
- Managed connectors continuously extract data from production databases, SaaS tools, event trackers, and APIs. These managed pipelines handle schema drift and API updates automatically, eliminating the need for fragile, custom-written extraction scripts.
- Cloud Data Storage and Warehousing
- The central repository serves as the single source of truth across the enterprise. Modern cloud warehouses and lakehouses store structured tables and raw semi-structured files alike, automatically balancing compute resources to maintain low-latency query speeds.
- Transformation and Modeling
- Once data is securely stored, transformation frameworks use version-controlled SQL to clean, standardize, and aggregate tables. This layer ensures metrics such as customer lifetime value or churn rate carry identical mathematical definitions across finance, sales, and product teams.
- Governance, Observability, and Data Quality
- To ensure reports remain dependable, modern stacks deploy automated data observability and cataloging. Automated tests detect missing records, unexpected null values, and pipeline schema changes before faulty calculations reach executive dashboards.
- Data Activation and BI Consumption
- The top layer puts verified data to work. It powers interactive self-service business intelligence dashboards, surfaces automated alerts in workplace messaging apps, feeds machine learning models, and uses Reverse ETL to push warehouse-calculated metrics back into operational CRM systems.
Core Strategic Benefits for Modern Businesses
Adopting a modern data stack delivers immediate operational returns:
- Faster time-to-insight: Business units access reliable reports and dashboards on demand, removing the dependency on technical backlogs for routine performance queries.
- Scalable cost optimization: Elastic cloud consumption pricing models allow businesses to pay strictly for the compute and storage resources they actually utilize, bypassing expensive, oversized on-premise hardware.
- Structural adaptability: Because each layer is modular, teams can upgrade individual tools or adopt emerging technologies without redesigning their underlying data architecture.
- Immediate AI and ML capability: Centralizing well-governed, clean data creates the high-quality baseline required to train generative AI systems and deploy predictive analytics successfully.
For a detailed blueprint of how to integrate modular components and scale cloud pipelines efficiently, read this comprehensive breakdown of modern data stack architecture and enterprise design.
Execution: Bridging Tools with Strategy
Purchasing subscriptions to modern cloud data tools does not automatically make an enterprise data-driven. Without disciplined data modeling, strict schema governance, and clear stakeholder alignment, organizations risk building expensive, chaotic cloud environments.
Maximizing the value of a modern data stack requires tying your data pipelines directly to business priorities. Standardizing metric definitions, auditing pipeline health, and prioritizing high-impact operational use cases ensures your cloud analytics infrastructure consistently accelerates enterprise growth.
READ MORE - https://priorise.co/blog/modern-data-stack-architecture/




















Sign in to leave a comment.