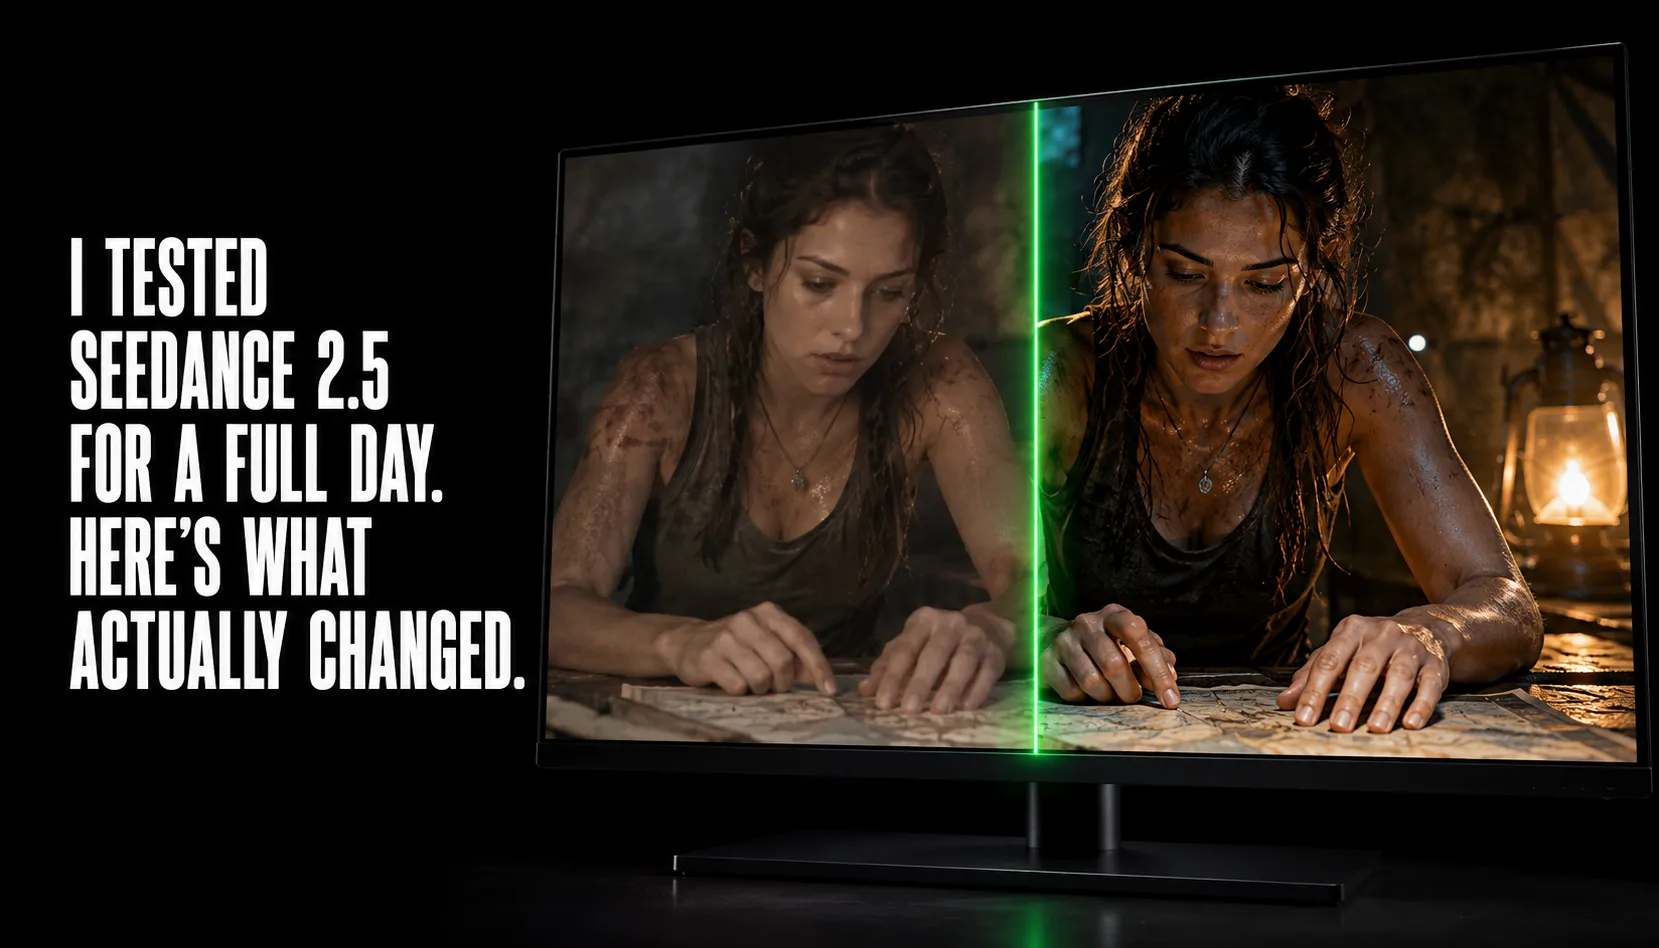

I work in AI-adjacent marketing tech, which means I get pitched a new "game-changing" model update roughly every other week. Most of them aren't. So when I saw that Seedance 2.5 had gone live inside UGCad AI, my first instinct wasn't to write about it it was to ignore the release notes entirely and just sit down and generate with it for a full day, on a real ad brief, the way I'd actually use it if I were running paid creative for a client.
This is the writeup from that day. Not a spec sheet recap, not a rewritten press release what Seedance 2.5 actually does when you put a real 30-second ad brief in front of it.
The Problem I Didn't Realize Was This Annoying Until It Was Gone
Here's something that's been quietly true of every AI video model I've tested, going back a couple of generations now: they all cap out somewhere around 10 to 15 seconds per single generation. That's fine if all you need is a quick hook test. It becomes a real problem the moment your brief calls for an actual 30-second ad, which and this is worth remembering happens to be the single most common ad length on both TikTok and Meta.
Before Seedance 2.5, getting to 30 seconds meant generating two separate clips and stitching them together. Clip one, clip two, and then however long it took in an editor to make them look like they came from the same shoot. Matching the lighting. Smoothing over the jump in energy where the second clip kicks in. Hoping the seam wasn't obvious to anyone watching on a phone screen with the sound off, which, let's be honest, is most of your actual audience.
I've done this stitch more times than I'd like to admit across different tools, and it's exactly the kind of manual work that quietly eats the time savings AI video generation is supposed to give you in the first place. You save time generating, then lose a chunk of it back in post. Net gain: smaller than it looks on a demo.
Seedance 2.5 removes that seam entirely. It generates the full 30 seconds in one continuous pass no stitching, no color-matching two separately generated clips after the fact. One generation, start to finish, same lighting and same energy the whole way through. I tested this directly with a testimonial-style brief, and the difference is obvious the moment you watch the output back. There's no point where the energy resets or the lighting shifts, because there was never a second clip to begin with. It sounds like a small thing described in a sentence. It is not a small thing when you're the one who used to do the stitching by hand.
What Seedance 2.5 Actually Is
Seedance 2.5 is ByteDance's newest video generation model, and structurally it's built around two things that marketers have been asking for pretty explicitly: longer single-take generations, and real creative control over what goes into them. If you want the reference version alongside this testing writeup, ByteDance has published the full technical spec sheet on the Seedance 2.5 model page I'd read this piece first, though, because a spec sheet won't tell you how it actually behaves under a real brief.
There are two things that separate it from every AI video model I'd tested before it. First, it generates up to 30 seconds in a single pass double the 15-second ceiling of Seedance 2.0. Second, and I think this is the genuinely underrated part, it reads up to 50 references at once: text prompts, multiple images, and audio, all understood together as one creative brief instead of one input type at a time.
That combined-reference part is what actually changed how I approach briefing the model. Before this, you were effectively choosing: describe the shot in words, or upload a reference photo, but not really both in any meaningful combined sense. With Seedance 2.5, you do both, plus a soundtrack if the moment calls for it, and the model treats all three as one instruction rather than three separate constraints fighting each other for priority.
Three Tests, and What Actually Came Back
I ran three specific tests on the day it launched, because I wanted to see the model's real behavior rather than take the release notes at face value. I'll walk through all three, because I think the differences between them are more useful than a single flashy example.
Test one: a full 30-second testimonial. I gave it a product brief and asked for a full testimonial-style ad hook, product reveal, close, all in one generation. What came back held the same presenter, the same setting, and the same lighting for the entire 30 seconds. No stitch point, because it never generated it as two separate pieces in the first place. This is the test that made the whole update click for me, because it's exactly the format where the old two-generation workflow used to cost the most editing time.
Test two: three reference angles of the same product. I uploaded three angles of a product bottle and asked for one continuous 360-degree rotation. The model held the lighting steady across all three angles, with no manual color-grading required afterward to smooth out the inconsistency you'd normally get generating each angle separately and hoping they matched later. This is the kind of detail that doesn't show up in a highlight reel but absolutely shows up in whether a video looks like a real product shoot or three renders duct-taped together.
Test three: audio-synced pacing. This is the one I genuinely didn't expect to work well. I dropped a trending audio track in alongside a product brief, and the motion and cuts in the output landed on the beat automatically. The previous version had no mechanism for this at all any beat-matched editing had to happen manually, after the fact, in a separate editor. This version reads the audio as an actual pacing reference, not just a track laid under a finished video after the fact.
What Actually Changed, Concretely
Most coverage of a model release stays frustratingly high-level, so I want to be specific about the four concrete changes that separate this version from its predecessor.
30-second single-pass generation. It doubles the previous 15-second ceiling without requiring a second generation or a manual stitch. This is the headline change, and it's the one that actually removes a real production bottleneck rather than improving output quality at the margins.
Up to 50 simultaneous references. It accepts text, images, and audio as one combined instruction set, rather than forcing a choice between description and reference material. The previous version handled one input type at a time; this one reads all of them together.
Audio-aware pacing. Feed it a track, and the motion and transitions in the generated video follow the beat. This is a genuinely new capability, not an incremental improvement on something that partially already existed.
Cross-reference consistency. Multiple product angles stay visually matched across a single continuous generation. Lighting, color, and product detail hold steady from the first frame to the last, even when the brief includes several reference angles of the same object.
Where This Actually Matters for a Real Ad Account
Testimonial-style UGC ads are the clearest fit. A full 30 seconds of a consistent presenter, the same setting, the same lighting throughout that's exactly the runtime where the old two-generation stitch used to cost the most editing time, and it's exactly where the single-pass duration pays off most directly.
Multi-angle product shoots are the second clear fit. If you're showing a bottle, a shoe, a device from three or four angles in one continuous piece of creative, the cross-reference consistency is built specifically for that, holding color and lighting steady across angles in a way that used to require manual grading between clips.
Anything audio-synced and trend-driven is the third. If your concept depends on a cut landing on a specific beat, this is currently one of very few models I've tested that reads the actual audio track as a pacing reference rather than requiring that timing to be built by hand afterward.
Where It Isn't the Obvious Pick
I want to be honest about this part, because most posts about a new model launch skip it entirely and just oversell the release. If your brief is a quick 3-to-5-second hook test with no audio-sync need and no multi-angle requirement, a faster, shorter model is probably still the more efficient choice for that specific render. The advantages here are concentrated in longer, more reference-heavy briefs it's not a strict upgrade for every single generation regardless of length.
Doubling duration while adding multi-reference support doesn't automatically mean every output beats the previous version in every dimension either. Stacking references toward that 50-reference ceiling works best with genuinely clear, specific direction vague prompts padded out with a dozen loosely-related inputs can still need a second pass to land correctly, even with everything the model can technically handle.
How the Workflow Actually Runs
Since I tested this inside UGCad AI specifically, it's worth walking through how the workflow actually runs end to end, because "there's a new model available" undersells what changed operationally.
You paste a product URL or write your own brief. Select Seedance 2.5 from the model picker instead of Seedance 2.0 or anything else. Upload your reference material a product photo, a few angles of the same product, a reference audio track and it reads all of it together, exactly like I described above from my own testing. Pick an avatar, or use a consistent AI presenter across every render. Then render, and it gives you back the full 30 seconds in one pass, ready to export in 9:16 for Meta or TikTok.
If you've already been generating on the platform with the previous model, nothing about the surrounding workflow changes now that this one is available. Existing scripts, existing avatars, existing briefs all carry over. Switching models is a dropdown change, not a new setup process the same hook generator and the same direct export options apply to every render exactly the same way they applied before.
That's the part I actually care about most, from a workflow angle rather than a pure model-capability angle. A model update that requires a new account, a new integration, or a new export process just to start using it quietly eats the time savings a longer single-pass generation is supposed to give you in the first place. The fact that it slots directly into a pipeline that already existed is, honestly, as much of the story as the model itself.
A Few Practical Notes From Actually Using It
Use the full 30-second window on purpose, not by default. The longer duration is a real advantage for testimonial and demo formats specifically. A quick hook test doesn't benefit from it the same way, and I wasted a render early on defaulting to the full length for a brief that didn't need it.
If exact packaging or label detail matters, pair a real product photo with your written brief. Text interpretation is genuinely improved over the previous version, but it still won't outperform an actual reference image for that level of specificity.
Keep your combined brief focused even when you're using several of the available reference slots. Three clear, specific reference images consistently outperformed a vague brief I padded out with a dozen loosely-related ones during testing.
And if you're testing anything audio-synced, feed it the actual track you intend to ship in the final ad, not a placeholder. The beat-matching behavior is tied to the specific audio you give it, so testing with a different track than what ships won't tell you how the real version lands.
The Actual Point
This update isn't interesting to me because it's a bigger number on a spec sheet. It's interesting because it removes a production bottleneck that's been part of AI UGC ad creation since the category started, and it does it while genuinely expanding how complex a creative brief can be without requiring a second generation to compensate.
If you're testing Seedance 2.5 yourself, I'd genuinely like to hear what you're seeing especially if it's different from what I found.
Frequently Asked Questions
What is Seedance 2.5 and how does it differ from Seedance 2.0?
Seedance 2.5 is ByteDance's latest AI video generation model that allows for 30-second single-pass video generation, doubling the 15-second limit of its predecessor, Seedance 2.0. Additionally, it can process up to 50 references at once, including text, images, and audio, which enhances creative control and streamlines the video creation process.
How does Seedance 2.5 improve video production efficiency?
Seedance 2.5 eliminates the need for manual stitching of clips by generating a full 30 seconds of video in one continuous take. This not only saves time in the editing process but also ensures consistency in lighting and energy throughout the video, addressing a common pain point in AI video production.
What types of ad briefs are best suited for Seedance 2.5?
Seedance 2.5 is particularly effective for longer, multi-angle ad briefs, such as testimonial-style ads or product showcases that require consistent lighting and energy. It is also beneficial for projects that need audio syncing with visual transitions, making it ideal for trend-driven video content.
Are there any limitations to using Seedance 2.5?
While Seedance 2.5 offers significant improvements, it may not be the best choice for very short clips, such as 3-to-5-second hook tests, where faster models could be more efficient. Additionally, vague prompts with numerous loosely-related inputs may still require a second pass to achieve the desired output quality.
How do I start using Seedance 2.5 in UGCad AI?
To use Seedance 2.5 in UGCad AI, simply paste your product URL or write your brief, select Seedance 2.5 from the model picker, and upload your reference materials. The workflow remains the same as previous models, making the transition seamless for existing users.
What are some best practices for generating videos with Seedance 2.5?
When using Seedance 2.5, it's advisable to focus on specific reference images and keep your brief clear, as this leads to better outcomes. Additionally, for audio-synced projects, ensure you use the actual track intended for the final ad to achieve accurate beat matching in the generated video.
Can Seedance 2.5 handle complex creative briefs effectively?
Yes, Seedance 2.5 is designed to handle complex creative briefs by integrating multiple input types—text, images, and audio—into a single coherent instruction set. This allows for more nuanced and creative outputs without the need for additional editing or generation passes.










Sign in to leave a comment.