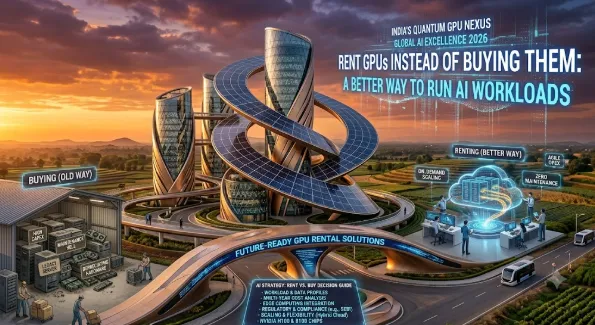

Every AI team eventually faces the same question:
Should we buy GPUs or rent them?
At first, purchasing hardware sounds attractive.
You own the machine.
You control the infrastructure.
There is no hourly meter running.
But AI workloads rarely behave predictably.
That changes the calculation.
AI Compute Demand Changes Constantly
A developer testing a small model might need modest compute.
A few weeks later, the same company might start fine-tuning a much larger model.
Suddenly the team needs considerably more GPU memory and processing power.
After the training run finishes, demand may fall again.
Buying infrastructure around peak usage means expensive hardware can remain underutilized for long periods.
Renting GPUs provides flexibility.
You provision the compute when you need it and release it when you do not.
Why Developers Rent GPUs
The most obvious reason is cost.
High-end data-center GPUs represent a significant upfront investment.
But another important reason is speed.
Buying infrastructure can involve procurement, installation, networking, configuration and software setup.
Cloud infrastructure can reduce many of those steps.
For an AI startup, shortening the distance between an experiment and a result can be more valuable than owning the underlying machine.
Renting Makes Experimentation Easier
AI development involves uncertainty.
You may not know which architecture will perform best.
You may not know how large your final model will become.
You may not know whether an experiment will last twenty minutes or twenty hours.
Flexible compute is useful precisely because developers do not need to know all these answers in advance.
Teams can experiment with different hardware configurations without committing to each configuration permanently.
For a more detailed look at choosing flexible GPU infrastructure, read our guide to GPU rental in India.
Which GPU Should You Rent?
The answer depends on the workload.
A100
Useful across many machine-learning training, fine-tuning and inference workloads.
H100
Designed for demanding modern AI workloads where performance is important.
H200
Provides significant GPU memory and can be valuable for very large or memory-intensive workloads.
Smaller GPUs
Inference, development and lighter AI workloads do not always need flagship hardware.
Choosing a smaller GPU can sometimes deliver a much better cost-performance ratio.
Renting GPUs in India
Location and billing can make a practical difference for Indian companies.
Many global infrastructure providers price services primarily in dollars.
That introduces an additional variable for teams whose revenues and budgets are primarily in rupees.
Indian developers increasingly have access to local alternatives.
For example, Race Engineering GPU Cloud provides GPU infrastructure focused on Indian AI builders, including access to H200, H100 and A100-class compute with INR billing.
This allows teams to think about infrastructure spending in the same currency as the rest of their operating budget.
Don't Compare Providers Only by Hourly Price
Suppose Provider A is slightly cheaper.
But a developer spends several hours configuring the environment every time a machine is created.
Provider B costs slightly more but provides an environment that is ready much faster.
Which one is really cheaper?
Engineering time has a cost too.
When evaluating cloud GPU rental, consider:
Provisioning time
GPU availability
Storage
Networking
Software setup
Billing structure
Reliability
Support
The lowest number on a pricing table is not necessarily the lowest total cost.
When Does Buying Make Sense?
Renting is not always the answer.
If an organization operates a highly predictable workload and expects to run GPUs continuously for years, hardware ownership may become economically attractive.
Large organizations may also want tighter control over infrastructure.
But many AI companies are still experimenting.
Their workloads change.
Their models change.
Their infrastructure requirements change.
Flexibility therefore has real value.
Compute Should Follow the Workload
AI infrastructure should adapt to the product rather than forcing the product to adapt to infrastructure.
Need additional GPUs for a large training run?
Scale up.
Finished training?
Scale down.
Testing something new?
Try another GPU.
This is ultimately why cloud GPU rental is becoming an important infrastructure model for AI development.
Conclusion
AI moves quickly.
Hardware procurement doesn't.
Renting GPUs gives developers a way to access powerful infrastructure without turning every new experiment into a long-term hardware decision.
For teams building the next generation of AI applications, that flexibility can be the difference between waiting for compute and actually shipping something.





















Sign in to leave a comment.