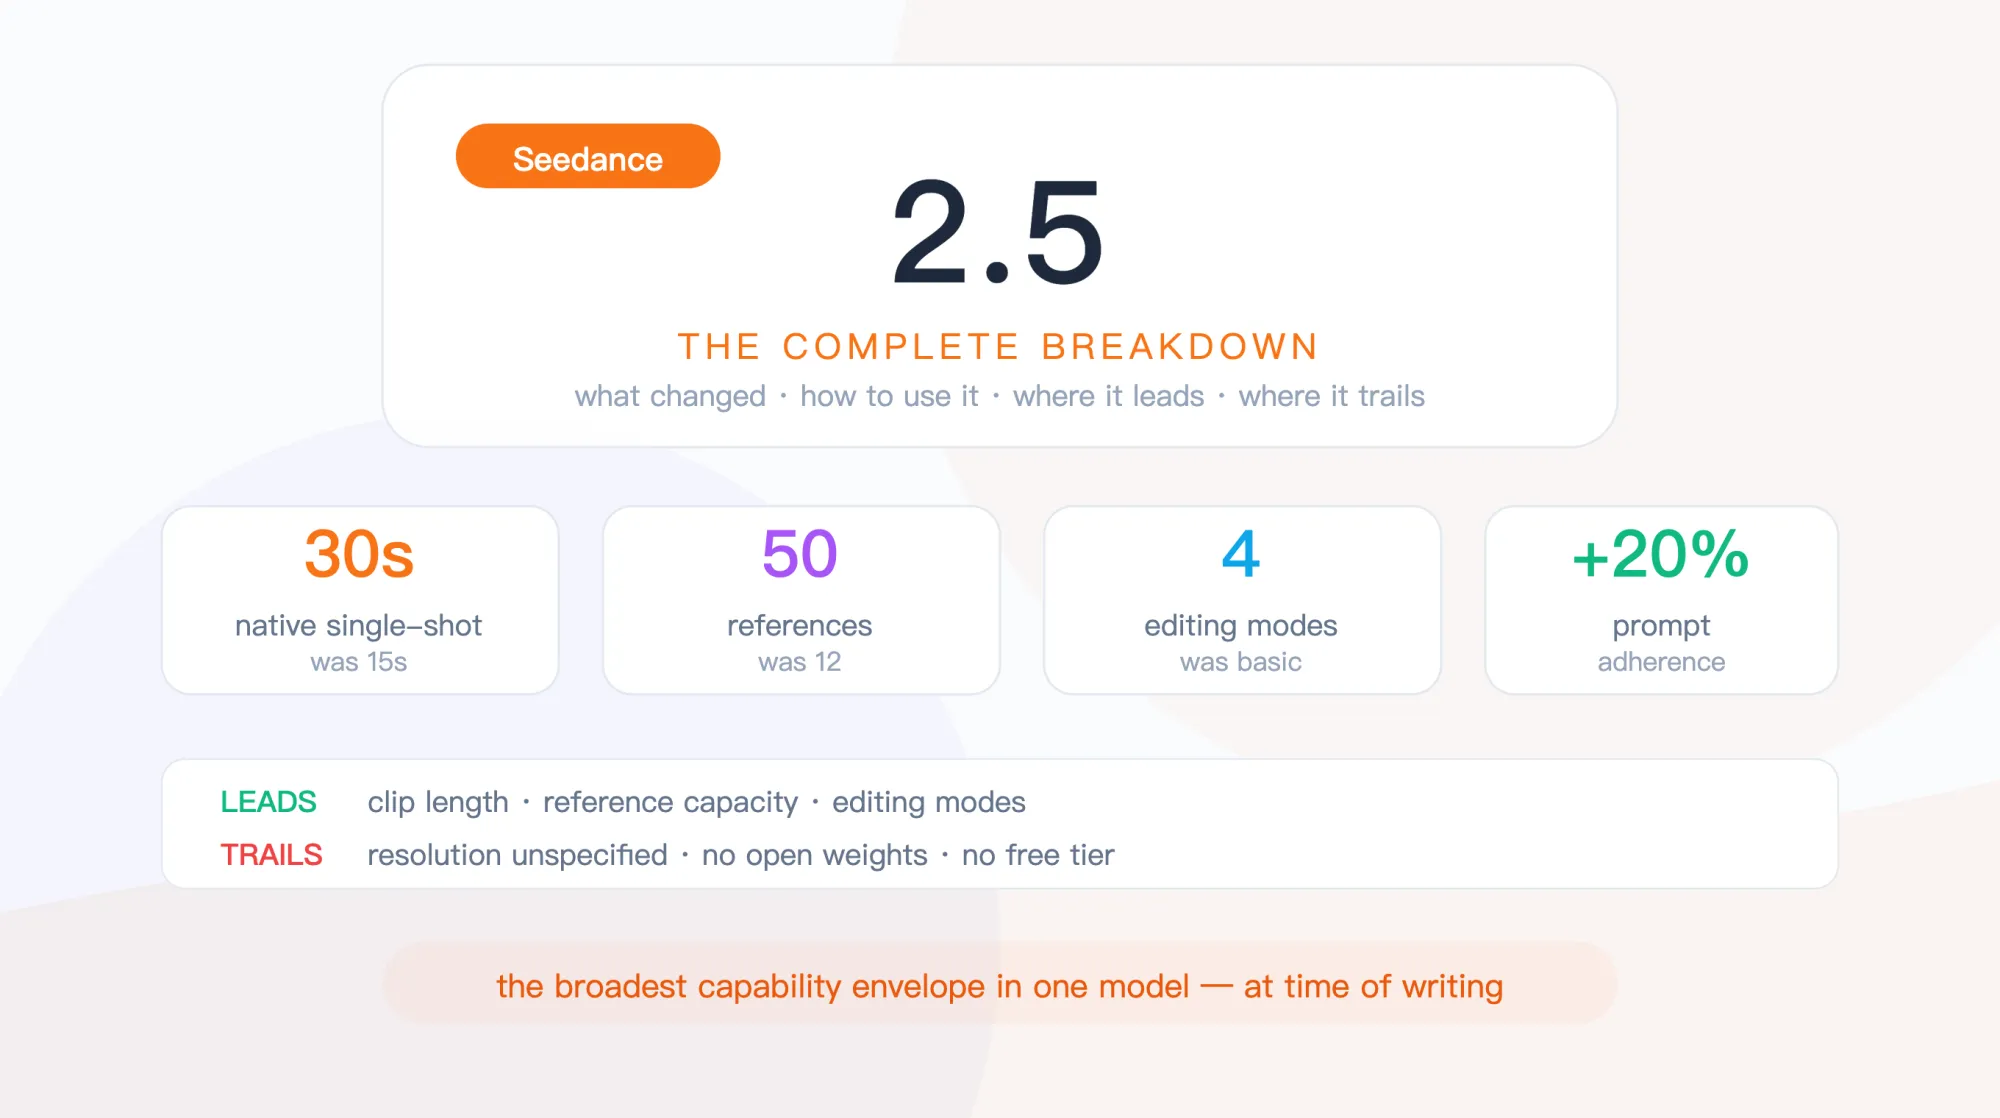

ByteDance released Seedance 2.5 on July 31, 2026, five weeks after its announcement at the Volcano Engine FORCE conference. The upgrade from Seedance 2.0 is substantial across every dimension that matters for content production. This article covers what changed, how to use it, where it excels, and where it falls short.
What Seedance 2.5 Is
A multimodal AI video generation model that accepts text, images, video clips, and audio files as combined input and returns up to 30 seconds of video with synchronized stereo audio in a single inference pass. More details at Seedance 2.5.
The Three Core Upgrades
Clip length: 15 seconds → 30 seconds. The previous 15-second limit required clip stitching for anything longer. Stitching introduced identity drift and lighting inconsistency at the seams. The 30-second native single-shot eliminates this problem entirely. Character, lighting, and narrative pacing remain coherent from start to finish.
The practical significance: 30 seconds is a standard TV ad, a complete YouTube Short, one chorus of a music video. Content that previously required multi-clip assembly now comes from a single generation. Extension supports two additional passes, and a beta ultra-long mode on the Jimeng platform has produced clips up to 180 seconds.
Reference capacity: 12 files → 50 files. The breakdown: up to 30 images, 10 video clips, and 10 audio clips per generation. ByteDance claims this is the largest reference capacity among comparable models.
At the FORCE conference, a demo showed 10+ actor references loaded simultaneously, with the model placing each character with spatial stability. Seedance 2.0's nine-image limit made ensemble scenes with more than four or five characters impractical. With 30 image slots, creators can separate identity, wardrobe, props, environments, and style references into distinct files with explicit role assignments.
The audio expansion from 3 to 10 slots enables independent control over BGM, sound effects, voice characteristics, and ambient sound — each with its own reference.
Editing: basic → four-mode suite. Timestamp-level control modifies specific time ranges without affecting the rest. Green screen replacement auto-segments backgrounds for environment swaps. Camera perspective re-editing changes camera angles or movement paths without regenerating content. Reference-based editing attaches existing clips and applies natural language modification instructions.
The practical impact: when 90% of a generation is approved but 10% needs adjustment, you fix the 10% without risking the 90%.
How to Use It
Access: Jimeng AI, Doubao Pro, and Dreamina are live now. BytePlus ModelArk API opens August 7. No free API quota — requires $30+ account balance.
Reference role assignment: Each uploaded file needs an explicit role in the prompt text. "Images 1-3 are protagonist identity. Images 4-6 are wardrobe references. Video 1 is camera movement reference. Audio 1 is background music." One file, one role. Ambiguous assignment degrades output quality.
30-second prompt structure: Unlike 15-second prompts, 30-second generation requires temporal structure. Opening (0-8s) handles scene setup and character introduction. Middle (8-20s) delivers core action or product moment. Closing (20-30s) provides resolution, hero shot, or call to action. Specify camera movement and sound cues for each segment.
Editing workflow: Generate the full 30-second clip first. Review and identify specific elements that need adjustment. Select the appropriate editing mode. Change one element per pass, evaluate, then proceed to the next adjustment.
Sound direction: The 10 audio slots reward specific direction. Name instruments, specify timing for sound events, note where silence should fall. Generic instructions like "appropriate background sounds" produce generic results. Specific direction produces layered, production-ready audio. 10+ languages are supported for dialogue.
Camera terminology: English cinematography terms produce the most reliable camera behavior. Low-angle tracking, push-in, orbital, crane, Steadicam, Dutch angle, whip pan.
Where It Leads
Clip length: 30 seconds native — no other model matches this. Reference capacity: 50 files — largest available. Editing: four structured modes — most comprehensive suite. Prompt adherence: approximately 20% improvement over 2.0.
Where It Trails
Resolution: officially unspecified. Multiple outlets reported native 4K, but this was Seedance 2.0's specification. The FORCE conference introduced both models simultaneously, causing confusion. ByteDance's official 2.5 page does not claim 4K output. Kling 3.0 clearly supports native 4K.
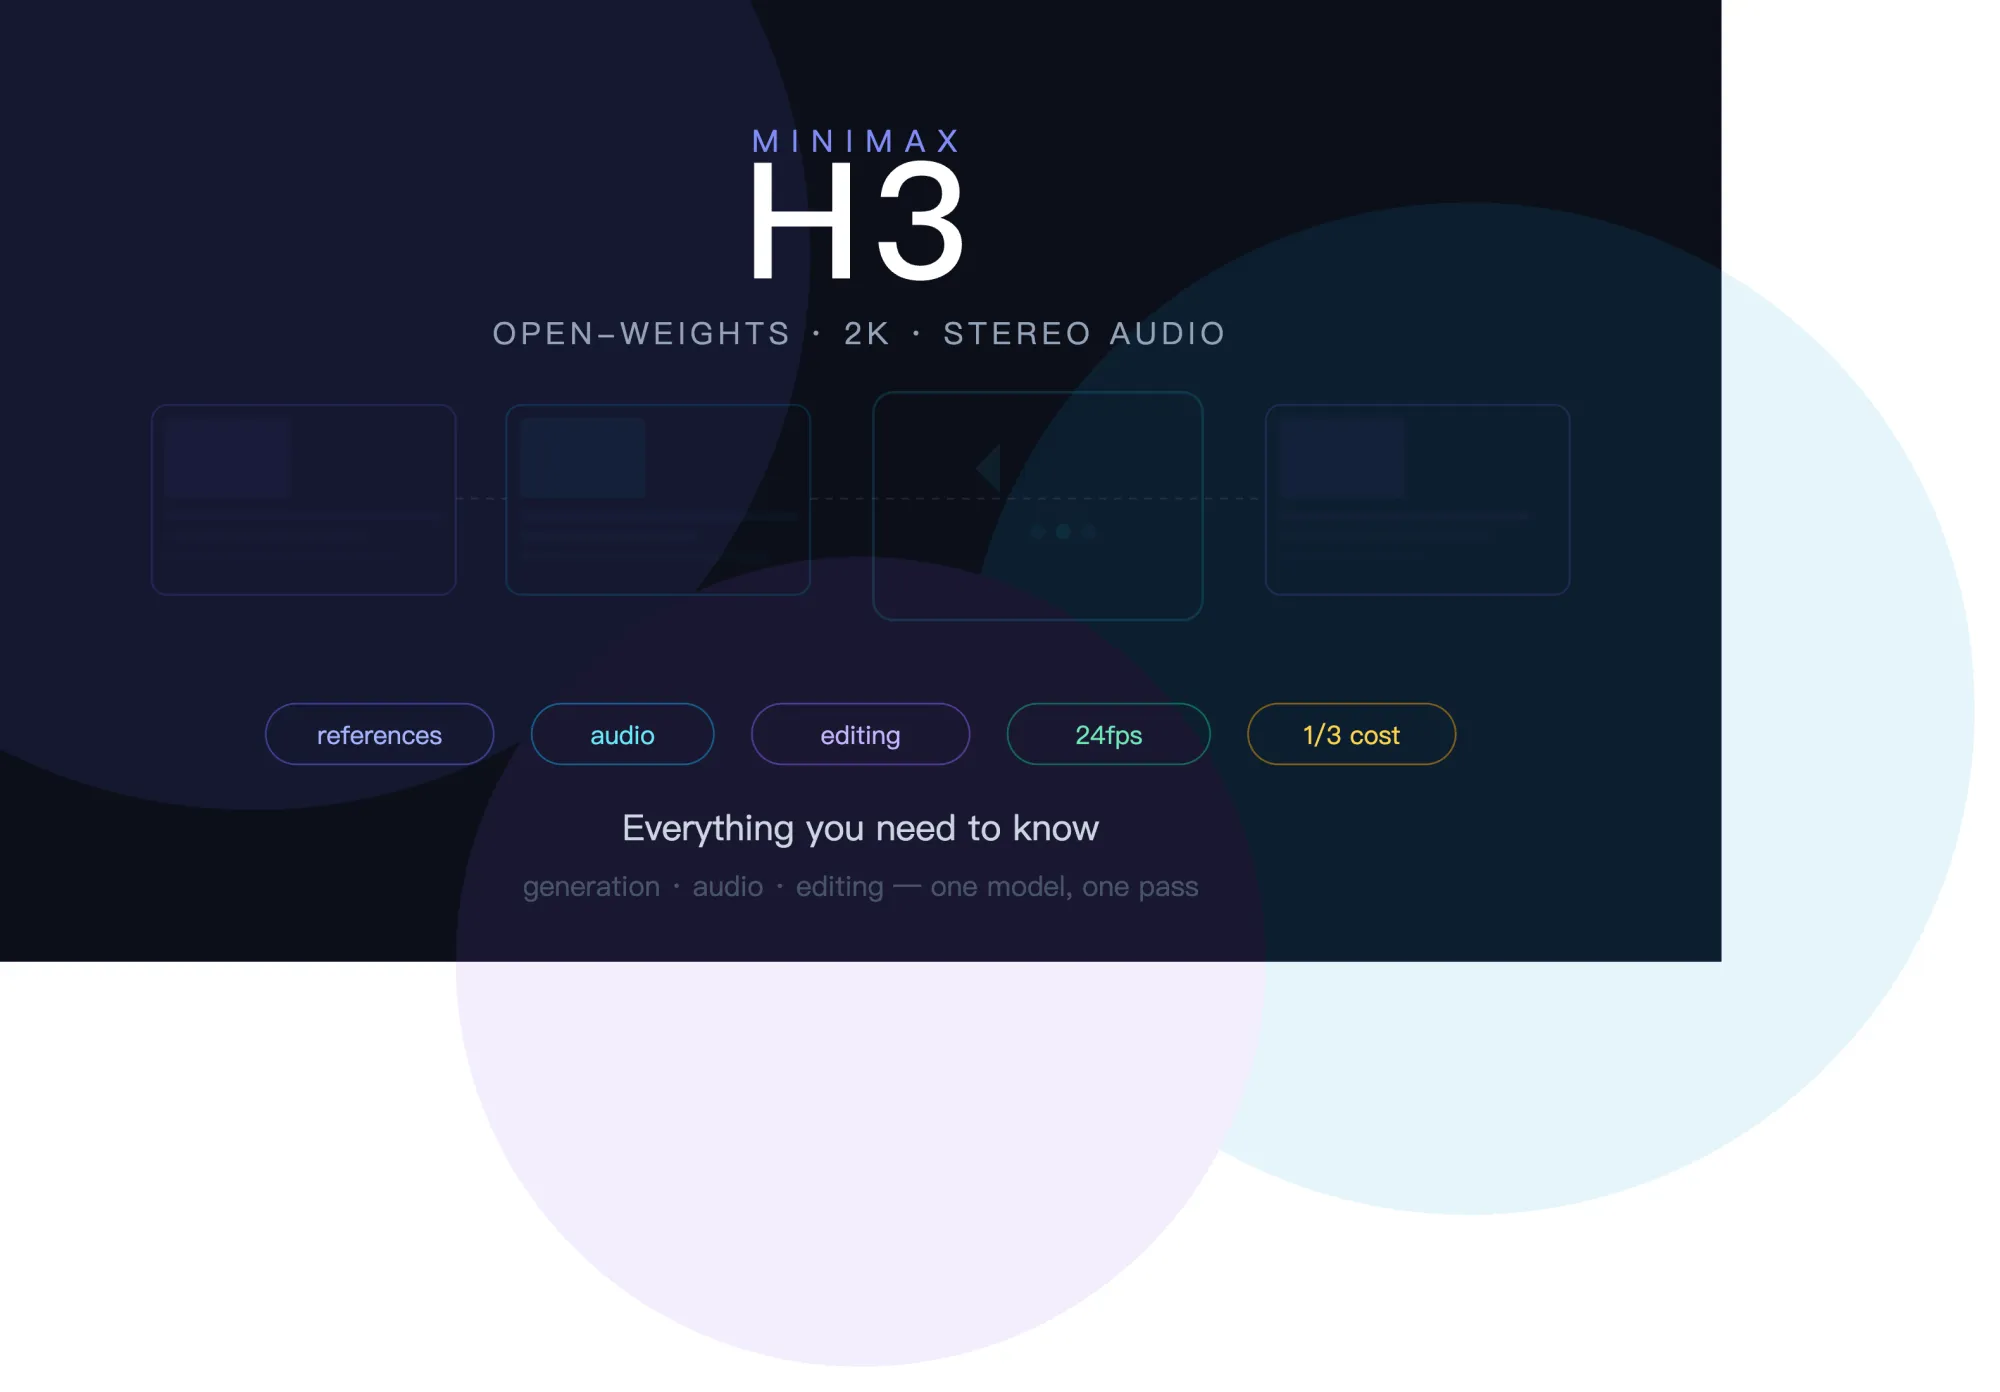
Open weights: not supported. MiniMax H3 has announced open-weight release. For developers wanting local deployment or fine-tuning, this is a meaningful gap.
Free tier: no free API quota. The $30 minimum balance creates an entry barrier for individual developers and small creators.
Independent benchmarks: not yet established. Seedance 2.0's launch scores (T2V ELO 1,269 / I2V ELO 1,351) were strong, but 2.5's independent evaluation is pending.
Competitive Landscape
Each frontier model differentiates on a different axis. Seedance 2.5 leads on length and reference control. MiniMax H3 leads on editing benchmarks and open-weight accessibility. Kling 3.0 leads on resolution. Veo 3.1 leads on dialogue audio quality. No single model dominates all dimensions.
Bottom Line
Seedance 2.5 pushes the boundary on what a single generation can produce. 30 seconds of coherent, audio-inclusive video from up to 50 reference inputs, with four editing modes for targeted revision — this combination is unmatched at the time of writing. The resolution ambiguity and lack of free tier are genuine limitations, but the capability envelope is the broadest available in one model.











Sign in to leave a comment.