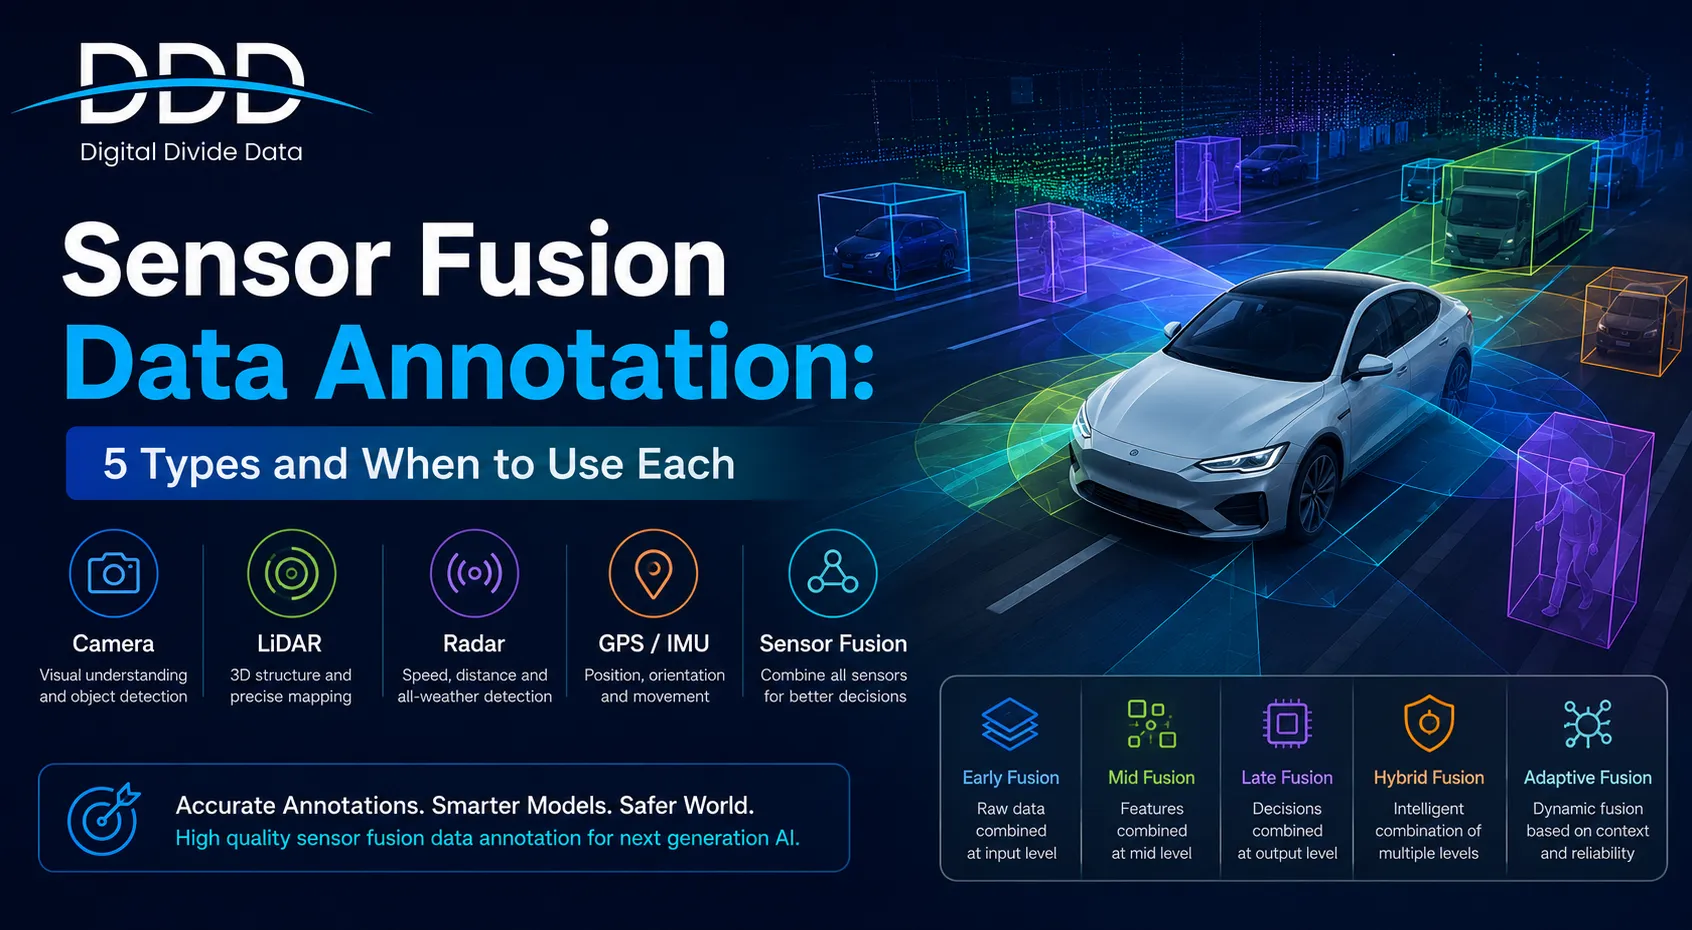

The global autonomous vehicle market is projected to reach $2.3 trillion by 2030, with perception AI as the central development challenge (Source: Statista, 2023). Every perception model in that market trains on annotated sensor data, and the annotation technique must match the AI task or the data is useless regardless of volume. Sensor fusion data annotation covers five distinct techniques, each producing a different type of label for a different layer of the perception stack. Choosing the wrong technique wastes budget and produces training data that cannot meet your model's requirements. This post breaks down each type, explains when to use it, and covers the quality standards each demands.

What Are the Types of Sensor Fusion Data Annotation?
The five core sensor fusion annotation types are 3D bounding box annotation, semantic segmentation, object tracking annotation, Bird's Eye View annotation, and radar object association. Each operates across sensor modalities rather than within a single sensor stream. Each requires cross-modal label consistency as the baseline quality standard. No technique substitutes for another because each answers a different perception question.
What Makes 3D Bounding Box Annotation the Foundation Technique?
3D bounding box annotation marks each object in a LiDAR point cloud with a cuboid label containing position, dimensions, orientation, and class. It is the core annotation type for spatial perception in sensor fusion. Every downstream task, from collision avoidance to path planning, depends on accurate 3D object positioning. It requires annotators trained in point cloud tools and automotive object taxonomy, and it must be validated against camera annotations for cross-modal consistency.
When Does Radar Association Add Value?
Radar annotation associates detected radar returns with object class labels and velocity measurements. It does not produce the spatial resolution of LiDAR or the visual detail of cameras. Its value is in two specific areas: object velocity measurement, which neither camera nor LiDAR can provide directly, and all-weather reliability, where radar maintains performance in conditions that degrade both visual sensors. Radar association is not a standalone annotation task. It is a fusion layer that extends the capabilities of LiDAR and camera annotation in adverse conditions.
When Should You Use 3D Bounding Box Annotation Over 2D?
Use 3D bounding box annotation when your model needs to know the precise location of an object in three-dimensional space: its exact distance, height, width, depth, and heading angle. Use 2D bounding box annotation when spatial depth is not required and the model only needs to classify and locate objects within a camera frame.
ADAS models for forward collision warning need 3D spatial data. Models for traffic sign recognition only need 2D classification. The difference determines whether LiDAR annotation is required or whether camera-only annotation is sufficient for the task. Adding LiDAR annotation when the model architecture does not use 3D data is wasted cost. Omitting it when the model needs spatial depth produces a perception system that cannot estimate distances reliably.
3D Annotation Precision Standards for Safety-Critical Models
For ADAS and autonomous driving models, 3D bounding box positional accuracy must meet sub-5cm error at the sensor's maximum operating range. At long detection ranges, small annotation errors translate to significant real-world distance misestimates. A 10cm positional error on a bounding box at 50 metres teaches the model to misjudge a vehicle's position by a margin that matters for emergency braking decisions. Production annotation providers for safety-critical programs document and report positional accuracy as a standard quality deliverable.
How LiDAR and Camera Annotations Are Cross-Validated
Cross-validation projects the 3D LiDAR bounding box onto the camera image plane using the extrinsic calibration transform. The projected box outline should match the 2D bounding box drawn on the camera frame within defined pixel and distance tolerances. Any mismatch beyond tolerance triggers annotator review and correction. This cross-validation step is what distinguishes sensor fusion annotation from independent per-sensor labeling, and it is the most effective single quality check in the pipeline.
What Is Bird's Eye View Annotation in Sensor Fusion?
Bird's Eye View annotation transforms fused sensor data into a top-down 2D representation of the environment and applies labels within that unified spatial frame. It is the standard annotation format for spatial reasoning, path planning, and navigation models in autonomous driving. BEV removes the perspective distortion present in camera images and provides a consistent coordinate system for objects detected by all sensor types simultaneously.
Annotating in BEV requires precise extrinsic calibration between all sensors. Calibration errors that appear small in raw sensor data become clearly visible in BEV representation, where objects from different sensor modalities must occupy the same spatial position. BEV annotation is also the format required by most modern multi-sensor 3D object detection architectures, making it a practical necessity for programs building on current-generation autonomous driving model frameworks.
HD Map Annotation as a BEV Reference Layer
HD map annotation creates centimetre-accurate road geometry, lane boundary, and traffic sign position data used as a static reference layer in BEV representations. Autonomous driving models fuse HD map data with live sensor inputs in BEV space to reduce per-frame scene reconstruction load. HD map annotation requires specialised road network knowledge and accuracy verification against survey-grade reference geometry. It is a distinct annotation discipline from object detection and must be treated as such in project planning and resource allocation.
BEV Annotation for Intersection and Complex Road Geometry
Intersections are the most challenging geometry in BEV annotation. Lane connectivity, signal positions, pedestrian crossing zones, and permitted vehicle paths must all be annotated within a consistent spatial reference. Errors in intersection BEV annotation teach navigation models incorrect path options that can lead to incorrect turn decisions or missed right-of-way rules. Intersection annotation requires annotators with specific road network knowledge and a detailed edge case handling schema.
How Does Object Tracking Work in Sensor Fusion Annotation?
Object tracking annotation assigns a persistent unique ID to each object across every frame of a video sequence, across all sensor modalities simultaneously. An object that appears in frame one must carry the same ID in frame five hundred, even if it is partially occluded, leaves the frame temporarily, or changes appearance due to lighting or weather. Cross-modal tracking requires that this ID is consistent across LiDAR, camera, and radar data for the same object in the same frame.
Tracking annotation is evaluated using MOTA (Multiple Object Tracking Accuracy), which measures ID consistency, missed detections, and false positives across a sequence. A MOTA score below 0.75 indicates tracking quality problems that will degrade model performance on any task requiring temporal object continuity: prediction, trajectory estimation, or dynamic occupancy mapping.
Object Re-Identification After Occlusion
When an object disappears behind another and re-enters the scene, the annotation must correctly re-assign the original ID. Incorrect re-identification, where the re-emerging object receives a new ID, teaches the model that a new object has appeared rather than that an existing one has returned. At scale, this corrupts the model's understanding of object continuity and degrades performance on motion prediction tasks. Annotation schemas must define explicit re-identification rules for occluded objects before annotation work begins. A full breakdown of how multi-sensor annotation pipelines handle tracking and occlusion for autonomous driving is available through this technical guide to multi-sensor data annotation for autonomous driving.
Which Sensor Fusion Annotation Type Is the Most Complex?
Semantic segmentation applied across fused sensor data is the most complex and most expensive sensor fusion annotation type. It requires assigning a class label to every pixel in every camera frame, cross-validated against LiDAR depth data for 3D scene understanding. A single complex urban frame can take 45 to 90 minutes to annotate at production quality standards (Source: IEEE Computer Vision and Pattern Recognition, 2022). At dataset scale, this makes full semantic segmentation significantly more expensive than bounding box tasks.
Panoptic segmentation, which combines semantic class labeling with instance-level object separation into a single unified map, sits above even standard segmentation in complexity. It is used in research programs and high-specification autonomous driving datasets but is not standard across all production ADAS development programs.
Conclusion
The five sensor fusion annotation types, 3D bounding boxes, semantic segmentation, object tracking, BEV annotation, and radar association, each answer a different perception question for a different AI task. No single type covers all requirements. Most production autonomous driving programs require all five applied to the same sensor sequences. Sensor fusion data annotation at production quality demands cross-modal consistency, systematic QA, and annotator expertise across all sensor modalities in scope. As autonomous systems move to higher automation levels, the annotation complexity will increase alongside the precision requirements of the models they train.







Sign in to leave a comment.