
AI technology is gradually integrating into the operations of businesses. Businesses have been deploying machine learning algorithms, generative AI tools, copilots, and AI agents to help in areas such as customer support, fraud detection, and forecasting among other functions.
However, one hidden challenge associated with AI technology includes the quality of the data being used.
A model can be technically sound and still produce unreliable results if the data behind it is incomplete, outdated, inconsistent, or affected by unexpected changes. This is one reason organizations are paying closer attention to AI observability platforms that can monitor not only whether a pipeline is running, but also whether the data and AI systems are behaving as expected.
What Is AI Observability?
Traditional observability has mostly been around observing infrastructure and performance of applications. There has always been monitoring of servers, applications, logs, APIs, and pipelines to detect problems and performance issues.
But AI observability goes beyond traditional observability.
With an AI observability platform, companies can learn about the state of the data and AI lifecycle. This could mean observing data freshness, schema changes, volume, distribution, pipeline activity, model input and output, and other signals that could influence the reliability of the AI application.
It's important because data issues usually don't lead to failures of a pipeline.
The process might go well while incomplete records of customers are pushed to a warehouse. The formatting of a column might change without creating any immediate problem. A data source might slowly drift from patterns used by an AI model.
While technically everything is green, the results might already be incorrect.
Why Data Quality Matters for AI
AI systems are highly dependent on the information they receive.
Consider a customer support AI assistant that relies on product, customer, and transaction data. If those datasets become stale or contain unexpected values, the assistant may still respond normally while providing inaccurate information.
The same issue can appear in predictive models. Changes in the distribution of incoming data can gradually affect model performance without producing an obvious system failure.
This is why AI observability needs to go beyond uptime and infrastructure metrics.
Organizations need visibility into questions such as:
- Is the data arriving on time?
- Has the schema changed?
- Are record volumes unusually high or low?
- Have important values started to drift?
- Are business rules still being followed?
- Which downstream reports or models could be affected?
- Can the source of anomalies be identified quickly?
- Are AI inputs and outputs behaving consistently?
Answering these questions helps data and AI teams move from simply monitoring systems to understanding whether the information produced by those systems can actually be trusted.
The Difference Between Data Observability and AI Observability
Data observability typically focuses on the health of data as it moves through pipelines and platforms. Common areas include freshness, volume, schema, distribution, lineage, and data quality.
AI observability expands this view to include the systems that consume and generate AI-driven outputs.
The distinction is becoming increasingly important as organizations introduce generative AI and agent-based applications into existing data environments.
For example, a data observability solution might identify that a source table has experienced a significant distribution change. An AI-focused observability approach can connect that change to the downstream model or application that depends on the affected data.
The goal is not simply to generate another alert.
The goal is to provide enough context for a team to understand the potential impact and determine what should happen next.
What to Look for in an AI Observability Platform
Organizations evaluating AI observability tools should look beyond the number of dashboards or alerts available.
A useful platform should provide visibility across several layers of the environment.
1. Data freshness and pipeline health
Late or failed data deliveries can quickly affect dashboards, models, and AI applications. Monitoring freshness and pipeline activity helps teams identify these problems before they become business issues.
2. Schema and data drift detection
Changes to columns, formats, values, or distributions can create unexpected downstream behavior. Automated drift detection can help teams identify these changes earlier.
3. Data quality validation
Monitoring metadata alone is not enough. Organizations may also need record-level checks, business rules, reconciliation, and accuracy validation to determine whether the data itself is fit for use.
4. Lineage and root-cause analysis
An alert is much more useful when it explains where the problem originated and what could be affected downstream. Lineage can help teams move from symptom to source more quickly.
5. AI input and output monitoring
As AI adoption increases, organizations need ways to evaluate the information entering models and agents as well as the outputs they generate. This provides an additional layer of control around AI reliability.
6. Actionable remediation
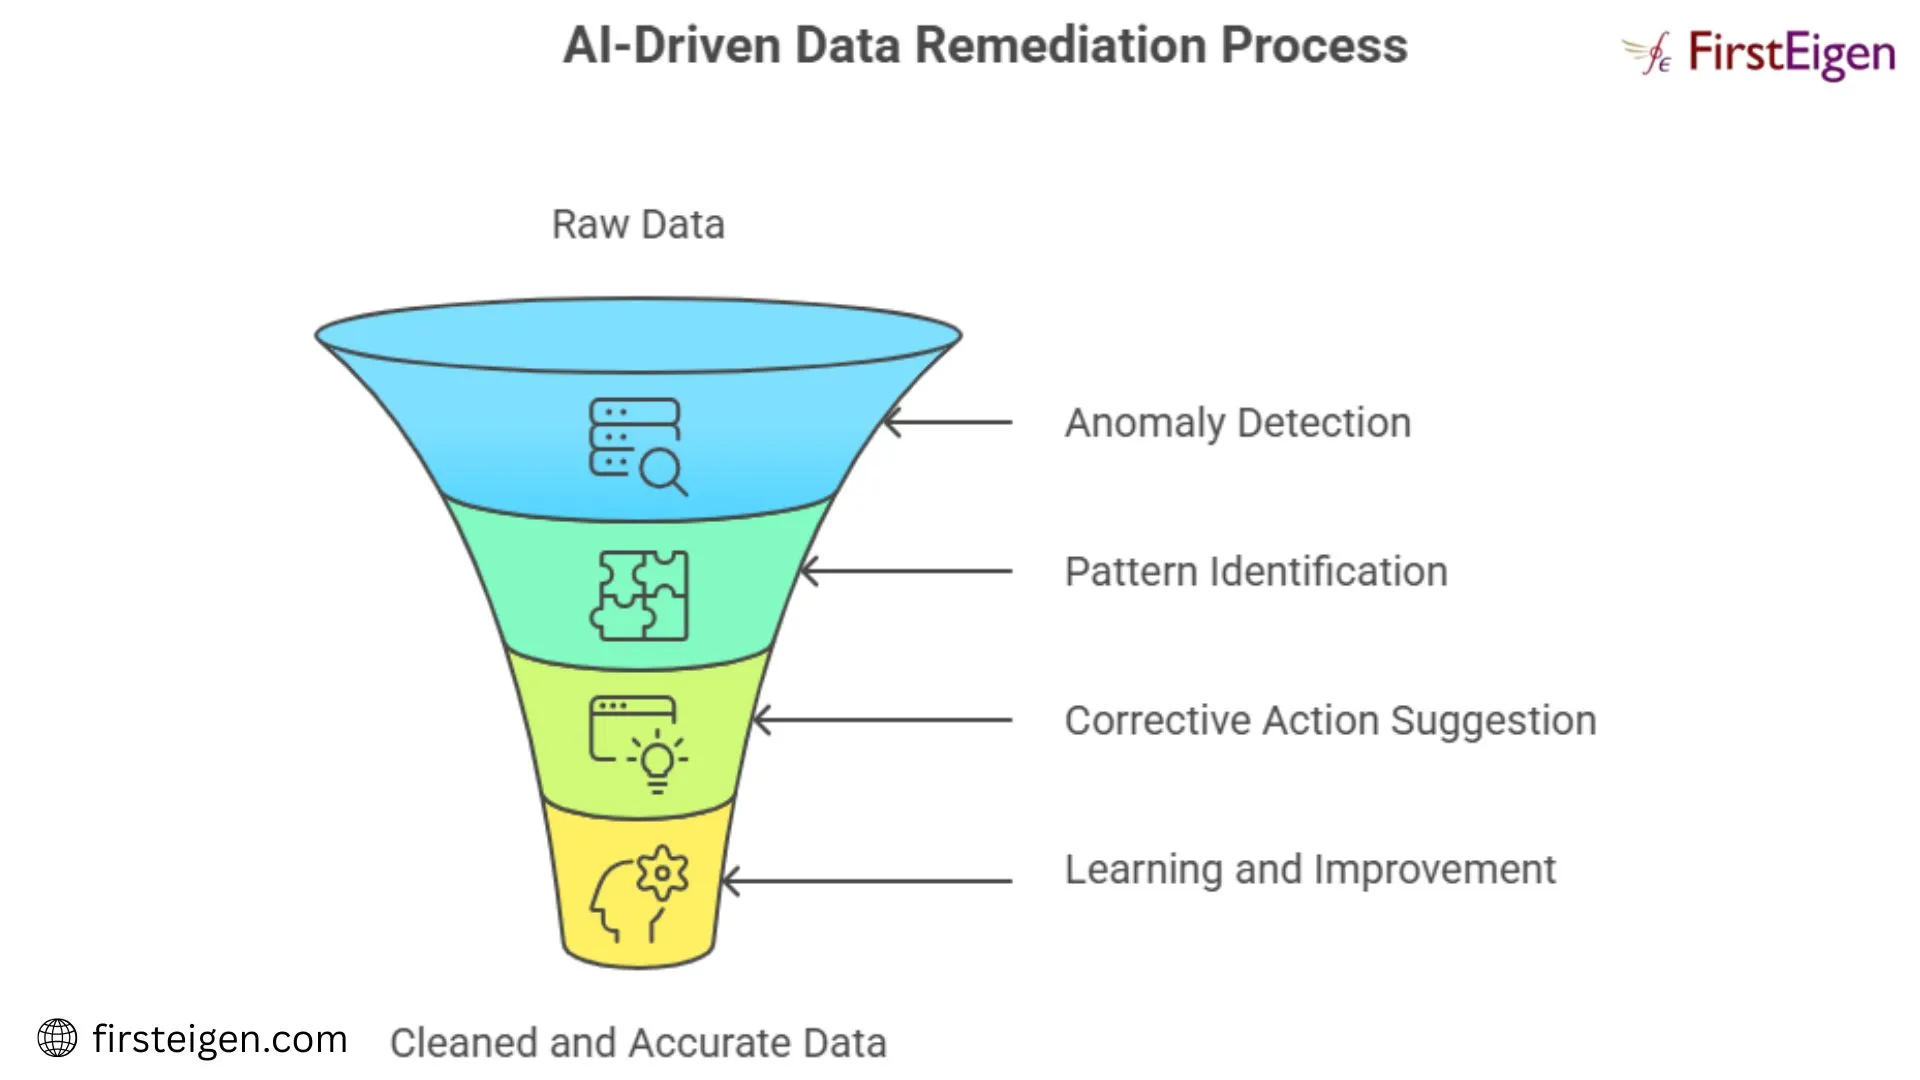
Detection is only the first step. The ability to route issues into existing workflows, investigate their cause, and support remediation can reduce the amount of manual work required from data teams.
Moving From Monitoring to Data Trust
One of the biggest changes in modern data management is the shift from asking, “Is the pipeline running?” to asking, “Can we trust the data coming out of it?”
This distinction is particularly important for AI.
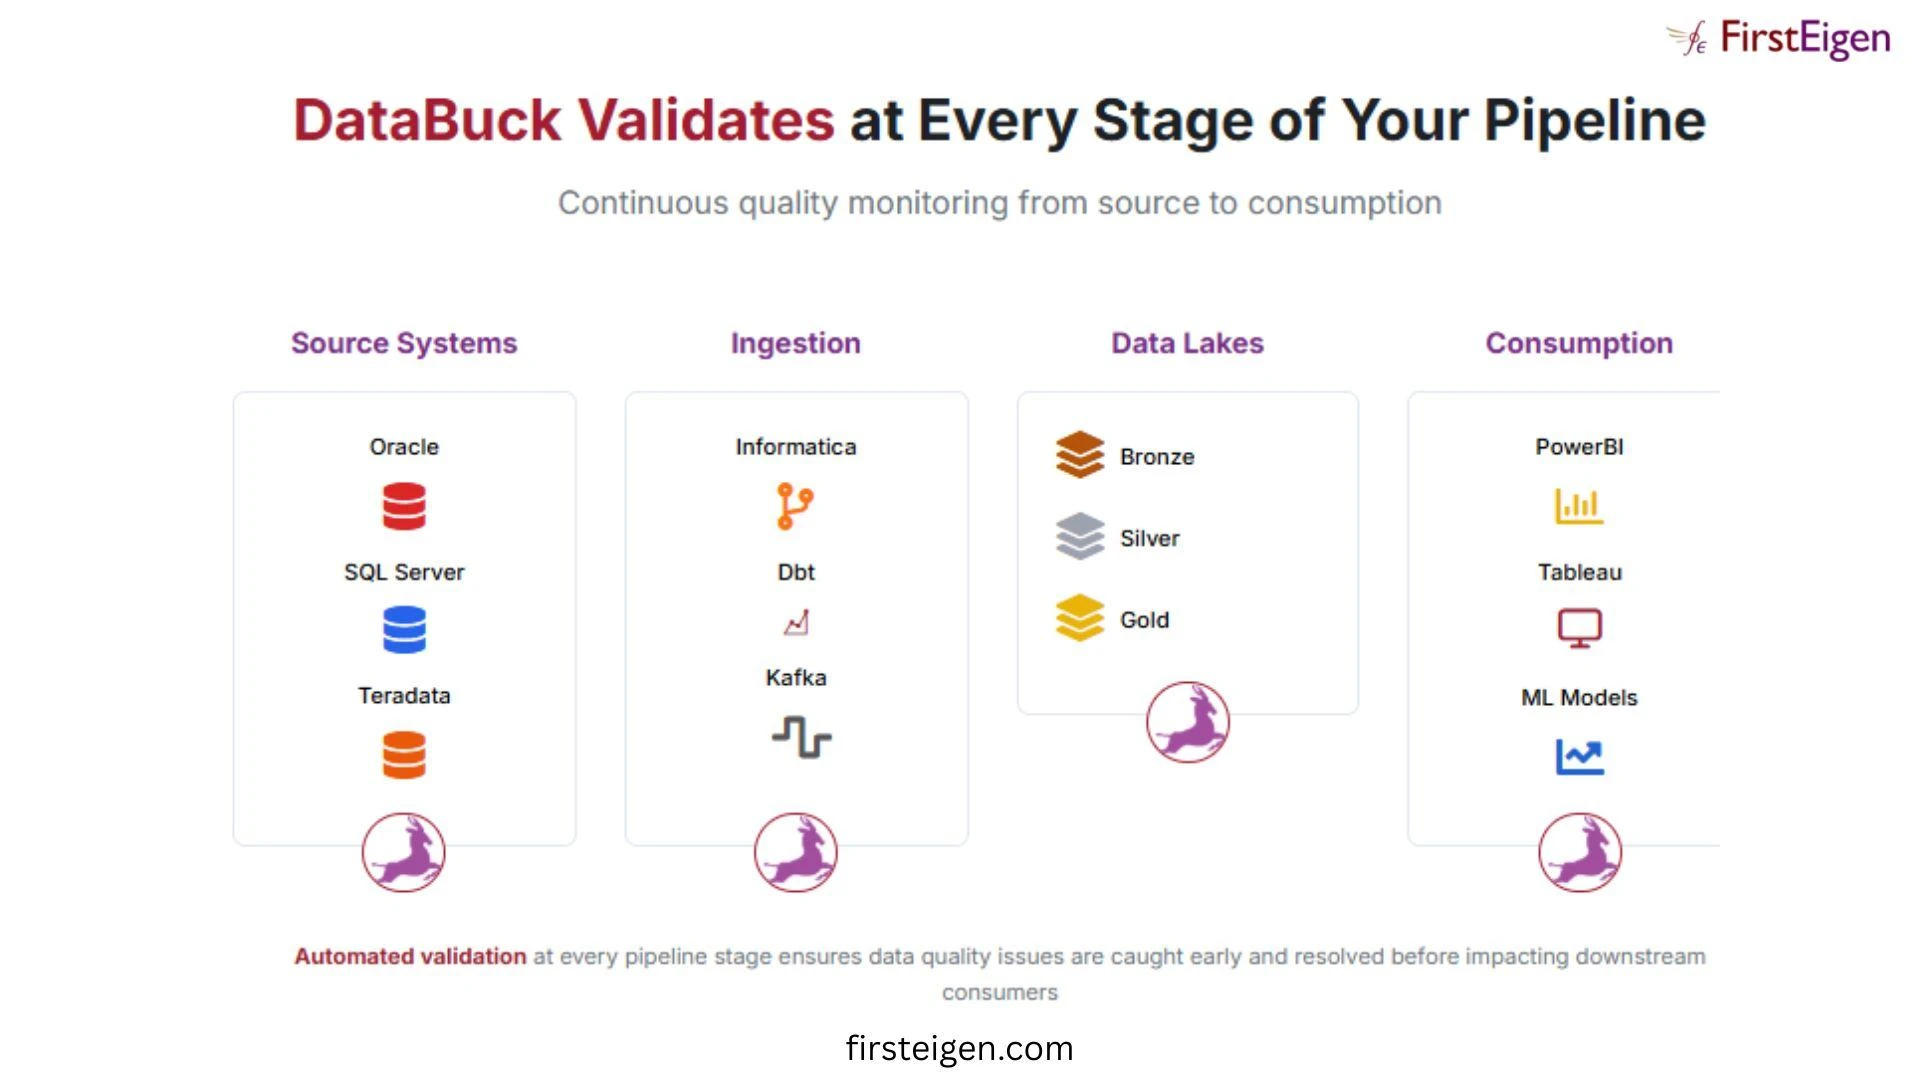
FirstEigen's DataBuck, for example, approaches observability across the broader data and AI stack. Its platform combines monitoring for areas such as freshness, volume, schema and distribution with data validation, lineage, trust scoring, and monitoring of AI inputs and outputs. This broader approach is designed to help organizations identify problems before unreliable data reaches downstream analytics or AI systems.
For organizations with large or complex data estates, that can be particularly valuable. Instead of relying on teams to manually create and maintain checks for every dataset, an AI observability platform can help automate the process of identifying unusual behavior and prioritizing potential issues.
Building More Reliable AI Starts with the Data
AI reliability is often discussed in terms of model architecture, infrastructure, or application design. Those factors certainly matter, but the data layer deserves equal attention.
A reliable AI strategy needs reliable input.
As data environments become more distributed and AI applications become more deeply integrated into business processes, organizations will need greater visibility across pipelines, datasets, models, and outputs.
That makes AI observability less of a niche monitoring capability and more of an important part of enterprise data management.
The organizations that build this visibility early will be better positioned to identify problems before they affect customers, reports, models, or business decisions.
In the end, the objective is straightforward: AI should not just be operational. It should be trustworthy.













Sign in to leave a comment.