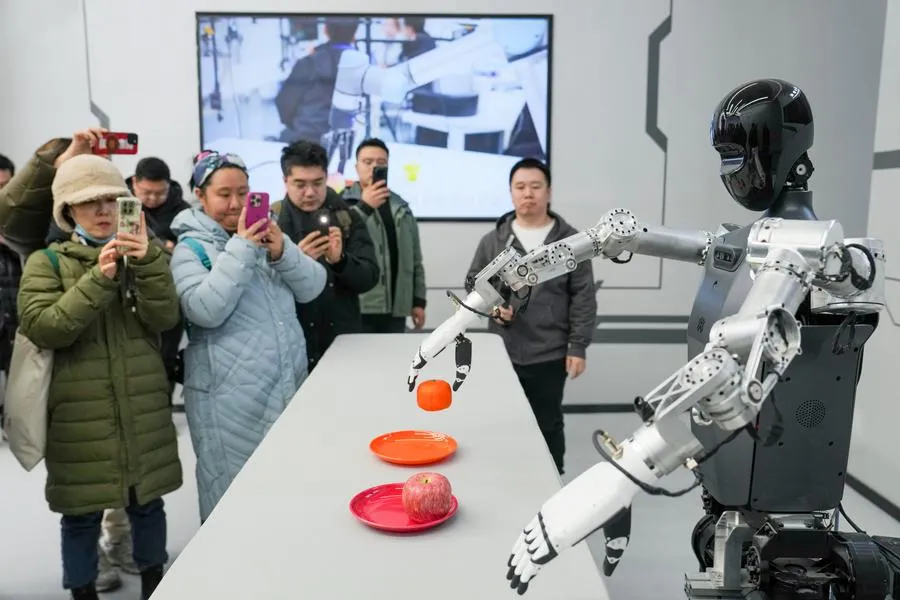

A humanoid robot make a cup of coffee with a coffee machine on a trade-show stage. The crowd applauds. Six months later, the same robot freezes when a part is rotated 15 degrees on an actual factory floor. The engineer's diagnosis is blunt: "It's never seen that angle before."
This gap between demonstration and deployment is the defining problem of the robotics industry in 2026.
Hardware has improved dramatically — domestic Chinese component costs for lead screws, reducers, and servo motors have fallen over 60% since 2023. Venture funding poured more than $4–5 billion into humanoid robotics in 2025 alone. Yet actual industry revenue sat at roughly $500 million the same year.
The robots exist. The money exists. What's missing is the data and the compute to make them genuinely useful.
1. The Physical-AI Data Famine
A 99.5% Gap That Can't Be Crawled
Large language models can be training from the content on public internet. Robot models cannot do that.
Large language models can also get the train content from the print books, magazines, and newspapers by scanner. Robot models cannot do that.
There is no public repository of "how a hand grasps a slippery bottle" or "what happens when a robot arm collides with a misplaced cable." Every physical interaction must be generated, recorded, and curated in the real world — one motion at a time.
According to industry figures reported by Robotsj, the total global volume of usable real-world physical interaction data is approximately 500,000 hours. The academic consensus, articulated by Yang Yaodong, Chief Scientist at LingChu Intelligence, at the LEAP East forum, is that embodied AI requires at least 100 million hours of human operation data as a foundational training set. That puts the current shortfall at 99.5%.
When viewed from the perspective of production speed, the situation is even less encouraging. The industry’s current annual output is approximately 1.6 to 1.8 million hours. At this rate, it would take 55 to 62 years to close the 100-million-hour gap.
"Data production itself is a capital-intensive manufacturing process." — Yang Yaodong, Chief Scientist, LingChu Intelligence
The Cost Per Hour Is Only the Beginning
Teleoperation — a human wearing VR headsets and haptic gloves, physically guiding a robot through tasks while sensors record every joint angle and camera frame — remains the gold standard for data quality. Costs have fallen sharply, from approximately $340 per hour in 2024 to around $118 per hour in 2026, per Haink's physical-AI knowledge base. But that figure covers collection only.
Once the raw data has been collected, the engineering team must clean, align, annotate, quality-check, and convert it. Industry experts estimate that the cost of this post-processing workflow is three to five times the cost of the initial data collection. In other words, for every $1 spent on data collection, an additional $3 to $5 must be spent to make the data suitable for training.
A June 2026 analysis by Live in the Future quantified the economics at AgiBot's Shanghai data factory, where 200 operators work 17-hour shifts across a converted warehouse:
| Metric | China (AgiBot) | U.S. Equivalent |
|---|---|---|
| Operators | 200 | 200 |
| Hourly wage (est.) | $6.00 | $30.00 |
| Annual labor cost | $5.3 million | $26.5 million |
| Output (data points/day) | ~40,000 | ~40,000 |
| Cost per data point | $0.51 | $2.55 |
For perspective, GPT-4's training cost roughly $0.0000077 per token. A single robot action sequence — one recorded grasp-and-place motion — costs between 66,000 and 330,000 times more per unit than a language-model training token. The comparison is not apples-to-apples, but the order of magnitude explains why data, not hardware, is where most robotics R&D budgets now go.
Data acquisition represents 60–80% of total development costs for humanoid companies, according to industry surveys cited by Humanoid Intelligence. Tesla's Optimus team reportedly spent over $50 million on teleoperation infrastructure alone in 2025. Boston Dynamics' Atlas successor required more than 100,000 hours of human demonstrations for basic manipulation. Only 20–30% of teleoperated sessions yield usable training data after quality filtering.
Simulation Helps — But Doesn't Close the Gap
Synthetic data from physics simulators like NVIDIA Isaac Sim and MuJoCo can generate millions of labeled episodes at near-zero marginal cost. A 2026 study from CMU and Stanford found that policies trained on a blend of 40% synthetic data matched policies trained on 100% real data on held-out tasks. That is a meaningful advance.
But the sim-to-real gap remains brutal. The Stanford HAI 2026 AI Index Report found that robots achieve 89.4% success on grasping and transport tasks in simulation, yet that figure collapses to 12.4% in real homes or factories — a 77-percentage-point drop. Simulated environments have consistent friction, even lighting, and neatly arranged objects. Real workshops have oil slicks, uneven floors, cluttered bins, and unpredictable humans.
"There is currently no clear viable path to generalization," Yang Yaodong noted. “Embodied AI robots have not yet reached a mature L2-level scaled application form.”
2. The Compute Bottleneck: Two Fronts, Same War
Even if the data problem were magically solved tomorrow, robots would still face a second wall: not enough compute, where it matters, when it matters. The shortage plays out on two distinct stages — the data center and the robot itself.
Data-Center GPUs: Training Capacity Can't Keep Up
Training modern vision-language-action (VLA) models—an architecture that integrates camera input, language commands, and motion output—requires GPU clusters comparable to those used for training large language models. To fully fine-tune OpenVLA (a model with 7 billion parameters), each GPU requires 48–80 GB of VRAM, and a multi-GPU configuration is recommended. Physical Intelligence’s π₀ series requires over 70 GB of VRAM for a full training run. NVIDIA’s GR00T N1.7 is recommended to be equipped with at least 40 GB of VRAM for fine-tuning.
Meanwhile, global GPU demand continues to vastly outstrip supply. A single large-scale AI data center consumes 500–1,000 megawatts of continuous power — roughly equivalent to a nuclear power plant. Global AI infrastructure spending is projected to exceed $1.8 trillion by 2030, according to analysis cited by TryRunable. U.S. data center power demand could reach 106 gigawatts by 2035, per BloombergNEF, a 36% upward revision from its forecast just seven months earlier.
Semiconductor manufacturing capacity from TSMC, Samsung, and Intel is ramping, but demand is growing faster. Spot rental prices for two-generation-old GPUs are rising — a classic signal of severe supply constraints. Robotics startups, which lack the capital reserves of hyperscalers, find themselves queued behind OpenAI, Google, and Meta for the same H100 and B100 allocations.
As a result, GPUs in data centers do not depreciate as quickly as we might expect, even if the next generation offers a 10-fold increase in performance. It is a good news for these small AI infrastructure company like Applied Digital, CoreWeave, MAAS, and Nebius Group.
Onboard Compute: The Edge Is Not Ready
The training-side shortage is severe but well understood. The less-discussed problem is what happens after training: running the model on the robot itself, in real time, with a power budget measured in watts, not kilowatts.
A 2026 arXiv study, "How Fast Can I Run My VLA?", benchmarked the π₀ VLA model across hardware tiers. The results are sobering for edge deployment:
| Hardware | End-to-End Latency | Inference Frequency |
|---|---|---|
| NVIDIA B100 (datacenter) | 3.18 ms | 314.4 Hz |
| NVIDIA H100 (datacenter) | 6.15 ms | 162.5 Hz |
| NVIDIA A100 (datacenter) | 16.20 ms | 61.7 Hz |
| NVIDIA Jetson Thor (edge) | 52.6 ms | 19.0 Hz |
Standard RGB cameras operate at 24–60 Hz. The Jetson Thor — NVIDIA's most advanced edge robotics platform, delivering 2,070 FP4 TFLOPS within a 130W power envelope — cannot keep pace. It falls below camera frame rates, meaning the robot is literally making decisions on stale images.
The root cause is memory bandwidth. The Jetson Thor uses LPDDR5X memory at 270 GB/s, optimized for low power consumption. Compare that to GDDR memory on an RTX 4090 at 1 TB/s, or HBM on a B100 at 8 TB/s. On the Thor, even the vision encoder — normally a compute-bound workload — becomes memory-bound, choking throughput across the entire pipeline.
Then there is thermal throttling. According to a May 2026 analysis by NicheFlash, sustained AI workload above 70% utilization triggers aggressive clock-speed reduction. In lab tests, a Thor module on a passive heatsink dropped from 2,070 TOPS to 980 TOPS within 18 minutes under a continuous three-camera plus LiDAR plus LLM inference load — causing intermittent motion stuttering in a walking robot prototype.
The Latency Hierarchy Problem
Robot control is not a single loop. It is a stack of control loops, each with its own deadline:
| Layer | Latency | Frequency |
|---|---|---|
| VLA inference (high-level decision) | ~150 ms | ~6 Hz |
| Upper-body control (arm motion) | 20 ms | 50 Hz |
| Locomotion / whole-body balance | 5 ms | 200 Hz |
| Joint servo drivers | 2 ms | 500 Hz |
Source: GR00T N1 + Unitree G1 architecture analysis, VNRobo, June 2026
You cannot run a VLA model end-to-end at 500 Hz. If you try feeding 6 Hz VLA output directly into joint servos, the robot jerks violently every 150 milliseconds and falls over. The industry's answer — decoupled architectures, where the VLA generates high-level targets at 6 Hz, a reinforcement-learning controller runs at 50 Hz, and a model-predictive locomotion controller closes the loop at 200 Hz — is sound engineering. But it adds enormous system complexity, and it means the VLA's slow inference cadence is a permanent ceiling on how quickly a robot can react to genuinely novel situations.
For a robot to respond to unexpected events—such as an object falling, a door suddenly opening, or someone entering its path—in a truly smooth, human-like manner, the VLA inference rate must reach 100 Hz. According to estimates from a study on arXiv, this would require approximately a fivefold increase over the current capabilities of the Jetson Thor. This gap must be bridged through model compression, quantization, reducing the number of diffusion steps, or by adopting a fundamentally new edge computing chip.
3. The Vicious Cycle
Data and compute are not independent bottlenecks. They feed each other in a punishing loop:
- More data requires more training compute, which is already in short supply.
- Larger models trained on that data require more onboard compute, which edge hardware cannot deliver.
- Slower onboard inference limits the complexity of tasks a robot can perform, which limits the range of real-world scenarios where robots can be deployed to gather more data.
- Less deployment means less diverse real-world data, which sends teams back to expensive teleoperation and imperfect simulation.
Compare this to autonomous driving. Waymo accumulated billions of miles of road data by deploying vehicles at scale, creating a flywheel where more cars generated more data, which improved the models, which enabled more deployment. Robotics has not reached that flywheel's ignition point. The current global installed base of humanoid robots is measured in the tens of thousands, not millions, and most are in research labs or controlled pilot deployments, not generating the messy, unscripted interactions that actually stress-test a model.
4. What's Actually Working
None of this means the industry is stuck. Several trends are bending the curve:
Synthetic data blends. The CMU/Stanford finding that 40% synthetic data can match 100% real data, combined with domain randomization techniques, is already reducing enterprise pilot budgets to roughly $50,000–$150,000 for the complete data-and-training stage — putting physical-AI pilots within reach of mid-market companies for the first time.
Automated expert generation. Frameworks like ExpertGen, published on arXiv in March 2026, automatically refine imperfect behavior priors into expert-level trajectories in simulation, potentially reducing real-world demonstration requirements by 90% compared to traditional behavior cloning.
Decoupled control architectures. NVIDIA's GR00T-WBC stack demonstrates that a 6 Hz VLA can coexist with a 200 Hz locomotion controller through hierarchical layering and action chunking — where the model predicts 16 steps ahead and the robot executes them while the next batch is inferred.
Specialized edge silicon. The Jetson Thor's 128 GB of unified LPDDR5X memory is a genuine step change from the Orin generation, enabling multiple models to run concurrently on a single board. Custom ASICs for edge inference are in development across multiple players, promising better performance-per-watt than general-purpose GPUs.
Conclusion
The reason robots remain hard to put to use is not a single missing technology. It is the collision of two scarcities that reinforce each other: the world cannot produce enough high-quality physical interaction data fast enough or cheaply enough, and neither data-center GPUs nor edge chips can keep up with the computational demands of the models that would consume that data.
Hardware is no longer the primary obstacle. The hard part is the unglamorous infrastructure — the data factories, the cleaning pipelines, the thermal management systems, the hierarchical control stacks — that sits underneath every smooth demonstration. As an industry, we are learning that building a robot body was the easy problem. Teaching it what to do, and giving it the horsepower to decide in real time, is the multi-decade project.










Sign in to leave a comment.