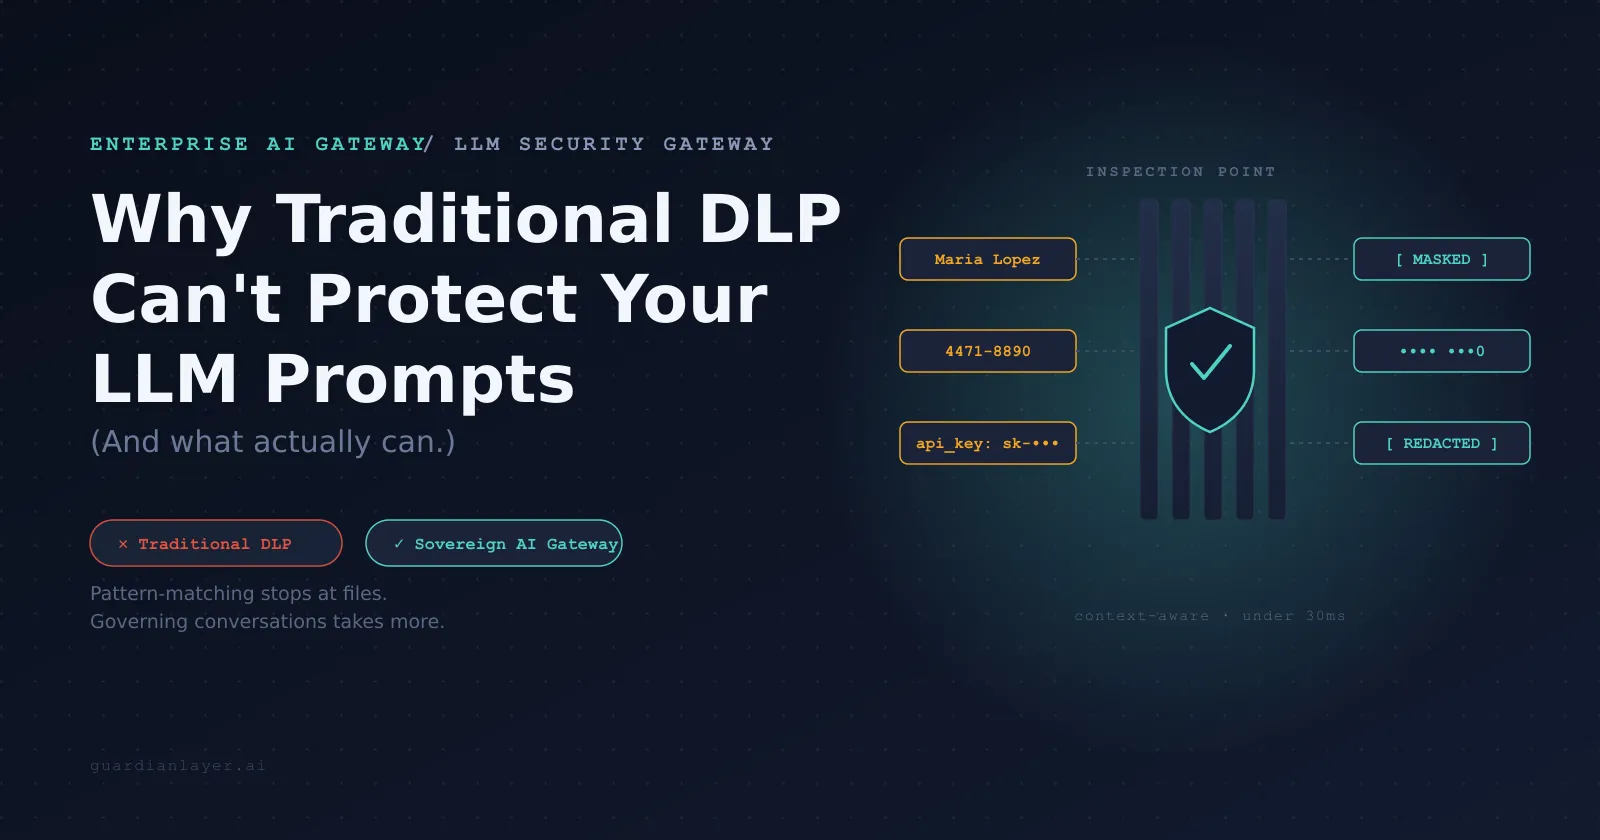

For two decades, Data Loss Prevention (DLP) tools have been the default answer to a simple question: how do we stop sensitive data from leaving the organization? They scan outbound emails, flag file uploads, and block network transfers that match known patterns like credit card numbers or social security formats. It's a model built for a world of files, forms, and predictable data flows.
Large language models don't live in that world.
When an employee pastes a customer's account details into a chatbot, or an AI coding assistant ingests a snippet of proprietary source code, or an autonomous agent chains together a dozen tool calls to complete a task none of that looks like a traditional data exfiltration event. It looks like a prompt. And prompts are exactly what legacy DLP was never designed to understand.
The Pattern Matching Problem
Most DLP systems work by matching data against static patterns: regular expressions, keyword lists, or fingerprinted documents. This works reasonably well for structured data like a 16-digit card number, but it breaks down almost immediately with natural language.
Consider a prompt like: "Summarize the dispute for our customer in account 4471, whose full name is on file under Lopez." There's no obvious pattern to catch here, no clean regex match yet this sentence could easily leak personally identifiable information (PII) once combined with context the model already has, or once the response comes back and includes details the user never should have received. Traditional DLP has no concept of conversational risk. It can't reason about intent, context, or the back-and-forth nature of an LLM interaction.
This is precisely the gap an Enterprise AI Gateway is built to close.
Prompts and Responses Aren't Files They're Conversations
An LLM interaction has two directions of risk: what goes into the model, and what comes back out. A prompt might contain trade secrets, source code, or health information typed in without a second thought. A response might inadvertently surface information the model was never supposed to reveal, or reflect a jailbreak attempt that slipped past a system prompt.
A purpose-built LLM Security Gateway inspects both directions in real time, using techniques far more sophisticated than keyword matching. Instead of relying only on regex, a hybrid approach combines pattern recognition with transformer-based semantic understanding so it can catch a customer's name phrased informally, a masked reference to a medical condition, or an injected instruction hidden inside retrieved context, all without breaking the structure or usefulness of the original text.
This matters because enterprise AI usage isn't confined to a single chatbot anymore. It spans custom GenAI apps, RAG pipelines, AI coding assistants, and increasingly autonomous agents that call tools and other models on their own. Each of those surfaces introduces a new path for sensitive data to leak or for malicious instructions to sneak through none of which a file based DLP tool was ever designed to see.
Governance, Not Just Blocking
The other limitation of legacy DLP is that it was built to make binary decisions allow or block a transfer with little nuance and even less audit value. Enterprise AI governance needs more: policy as code enforcement that varies by team, role, and model; immutable, hash-chained logs that hold up during an audit or incident response; and visibility into which employees, agents, or services are calling which models, at what cost, and with what outcome.
This is where a Sovereign AI Gateway approach earns its name. Rather than routing sensitive traffic through a third-party SaaS inspection layer, a sovereign deployment sits entirely inside your own infrastructure your cloud, your VPC, or on-prem so prompts, responses, and audit records never leave your control. When calls do go to external providers like OpenAI or Anthropic, the gateway can mask or block sensitive content before it's transmitted, giving security teams the same kind of perimeter control they've always had over network traffic, but rebuilt for AI.
What This Looks Like in Practice
In an effective setup, every prompt is inspected inline before it reaches a model, sensitive fields are masked without disrupting the request's structure, and every decision — allowed, masked, or blocked is logged with a tamper-evident record. Failover, model access rules, and spend tracking all run through the same policy layer, so security and cost governance aren't bolted on as separate tools.
Traditional DLP will keep doing what it does well: protecting files, endpoints, and network egress. But it was never built to reason about a conversation, understand semantic intent, or govern an autonomous agent's tool calls. As LLMs become embedded across the enterprise, closing that gap requires infrastructure designed specifically for AI traffic from the ground up not a retrofit of yesterday's controls.
That's the fundamental shift: from inspecting files at rest, to governing conversations in motion.














Sign in to leave a comment.