

Artificial intelligence depends on high-quality data to learn patterns, understand information, and produce accurate results. The quality of training data plays an important role in how well an AI model performs in real-world situations. Custom datasets training helps businesses prepare data that matches their specific goals, industry needs, and project requirements. Instead of relying only on general datasets, organizations can use relevant examples that teach AI systems to handle particular tasks.
An experienced AI training data provider helps collect, organize, label, and review data for machine learning projects. This process supports better model learning and reduces errors caused by incomplete or incorrect information. From natural language processing to computer vision, well-prepared datasets help developers build AI systems that understand different types of input. A clear data strategy also makes it easier to manage projects, improve quality, and prepare models for practical use.
Understanding Custom Datasets Training
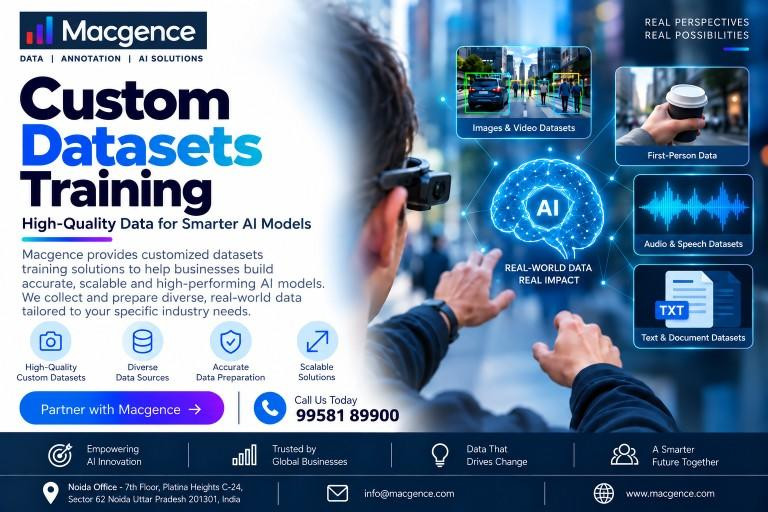
The process of preparing and using data designed for a specific AI application. The data may include text, images, videos, audio recordings, documents, or sensor information. Each dataset is created according to the model's purpose and the problems it needs to solve.
For example, a retail company may need product images to train an AI system to identify items on shelves. A healthcare technology company may require properly prepared medical documents for a document-processing model. A speech recognition system may need audio recordings from different speakers, accents, and environments.
General datasets may not contain enough examples of these specialized situations. Custom data fills these gaps by providing relevant information for the intended task. It also allows teams to define clear labeling rules, maintain consistent formats, and check data quality before training begins.
Why High-Quality Training Data Matters?
AI models learn from the examples included in their training data. Poor-quality information can create confusion, reduce accuracy, and lead to unreliable predictions. Missing labels, duplicate records, incorrect annotations, and unbalanced examples can affect the final model.
A reliable AI training data provider helps address these problems through structured data preparation and quality checks. The process can include reviewing source data, removing unnecessary records, correcting labeling mistakes, and checking whether the dataset represents different real-world conditions.
High-quality data also helps developers evaluate model performance more effectively. When the training examples are relevant and consistent, teams can identify weaknesses and improve their models with greater confidence. Data quality does not guarantee perfect results, but it provides a strong foundation for reliable AI development.
Key Steps in Preparing Custom AI Datasets
Building useful datasets requires a clear process that connects data collection with the model's learning objectives. Each stage helps ensure the information is relevant, consistent, and suitable for training.
1. Define the Project Goals
The first step is to understand the problem the AI model needs to solve. Teams should identify the required data types, expected outputs, target users, and performance goals. Clear requirements help prevent unnecessary data collection and keep the project focused.
For effective custom datasets training, the dataset should reflect the model's actual tasks. A chatbot may need question-and-answer examples, while an object detection model may require labeled images showing different objects, backgrounds, and lighting conditions.
2. Collect Relevant Data
Data collection involves gathering information from suitable sources according to project requirements and applicable privacy rules. Sources may include licensed datasets, approved recordings, business documents, images, videos, and sensor readings.
An AI training data provider can help organize this stage by following defined collection guidelines and checking the relevance of the available information. The collected data should represent different situations so that the model can learn beyond a limited set of examples.
3. Annotate and Label the Data
Annotation gives meaning to raw information by adding labels, descriptions, categories, or other useful details. Image annotation may involve bounding boxes, polygons, and segmentation masks. Text annotation can identify named entities, sentiment, or user intent. Audio annotation may include speech transcription and speaker identification.
Accurate annotation is essential for custom datasets training because models depend on these labels to learn the correct relationships. Clear instructions, trained annotators, and regular reviews help maintain consistency throughout the dataset.
4. Review Data Quality
Quality assurance helps identify incorrect labels, missing information, duplicates, and formatting problems. Reviewers can compare annotations against project guidelines and correct issues before the data reaches the training stage.
A structured quality process also helps teams measure agreement between annotators and identify areas that require additional training. These checks make the dataset more dependable and help reduce avoidable errors during model development.
Industries That Benefit From Custom Training Data
Different industries need different types of AI training information. A carefully prepared dataset helps models learn the patterns and details that matter to each application.
In healthcare, AI systems can use properly authorized and protected medical data to support document processing and selected image analysis tasks. In retail, labeled product images and customer interaction data can support product recognition and demand analysis. Manufacturing companies can use sensor readings and equipment images to identify possible faults and monitor production processes.
Autonomous driving and robotics also depend on varied real-world examples. Cameras, LiDAR sensors, and video recordings provide information about roads, obstacles, people, and moving objects. Custom datasets training helps developers prepare these examples for tasks such as object detection, scene understanding, and navigation.
Choosing the Right AI Training Data Partner
Selecting the right data partner can influence project quality, delivery timelines, and the ability to manage growing data requirements. Businesses should consider several important factors before making a decision.
First, review the provider's experience with the required data type, such as text, images, audio, video, or multimodal information. The team should understand the annotation methods and quality standards needed for the intended application.
Second, check the data security process. Sensitive information should be handled according to applicable privacy requirements, access controls, and agreed data protection procedures. Clear communication about ownership, usage rights, and storage is also important.
Third, evaluate scalability and flexibility. A project may begin with a small dataset and later require millions of records. The partner should have a clear process for maintaining quality as the volume grows.
A dependable AI training data provider should also offer transparent quality checks, consistent documentation, and delivery formats that fit the development team's workflow. Businesses can review sample annotations, test a small batch, and agree on acceptance criteria before expanding the project.
Macgence is associated with AI data services that support dataset preparation and annotation needs across different applications. Businesses can assess their specific project requirements, data formats, and quality expectations to determine the most suitable approach.
Common Challenges in Dataset Preparation
Dataset development can involve several challenges. One common problem is data imbalance, where some categories have many examples while others have very few. This can make a model perform well on common cases but struggle with less frequent situations.
Another challenge is inconsistent labeling. Different annotators may interpret the same example differently without clear guidelines. Detailed instructions, reference examples, and review procedures help reduce this problem.
Data privacy and licensing also require careful attention. Teams must confirm that data can be collected and used for the intended purpose. Removing unnecessary personal information and restricting access can help protect sensitive records.
Finally, datasets need regular evaluation and updates. As applications change, older examples may no longer reflect current conditions. Ongoing custom datasets training allows teams to address data gaps, include new scenarios, and improve the relevance of future training cycles. Monitoring real-world performance can help identify which changes are necessary.
Frequently Asked Questions
1. What is custom datasets training?
Custom datasets training involves preparing and using data designed for a particular AI task. It helps models learn from relevant examples, including specialized images, text, audio, video, and sensor information.
2. How does an AI training data provider help businesses?
An AI training data provider can support data collection, annotation, formatting, quality checks, and dataset management. These services help development teams obtain structured information that meets their project requirements.
3. Which data types can be used to train AI models?
AI models can use text, images, audio recordings, videos, documents, sensor readings, and combinations of these formats. The required data type depends on the application's goals and the model's intended functions.
4. How can businesses improve training dataset quality?
Businesses can define clear project requirements, use consistent annotation guidelines, remove duplicate records, review labels, protect sensitive information, and evaluate the dataset before training. Regular updates can also help maintain relevance.
Conclusion
High-quality data is a key part of developing useful and reliable artificial intelligence systems. From defining project goals to collecting, labeling, and reviewing information, every stage contributes to better model learning. Custom datasets training helps organizations prepare relevant examples for specialized applications, while careful quality checks support consistency and reduce avoidable errors.
Choosing an experienced AI training data provider can simplify data preparation and help teams manage complex requirements. By focusing on data accuracy, privacy, scalability, and regular evaluation, businesses can build stronger foundations for their AI projects and adapt their datasets as technology and application needs evolve.
Visit now: https://macgence.com/custom-datasets-training/













Sign in to leave a comment.