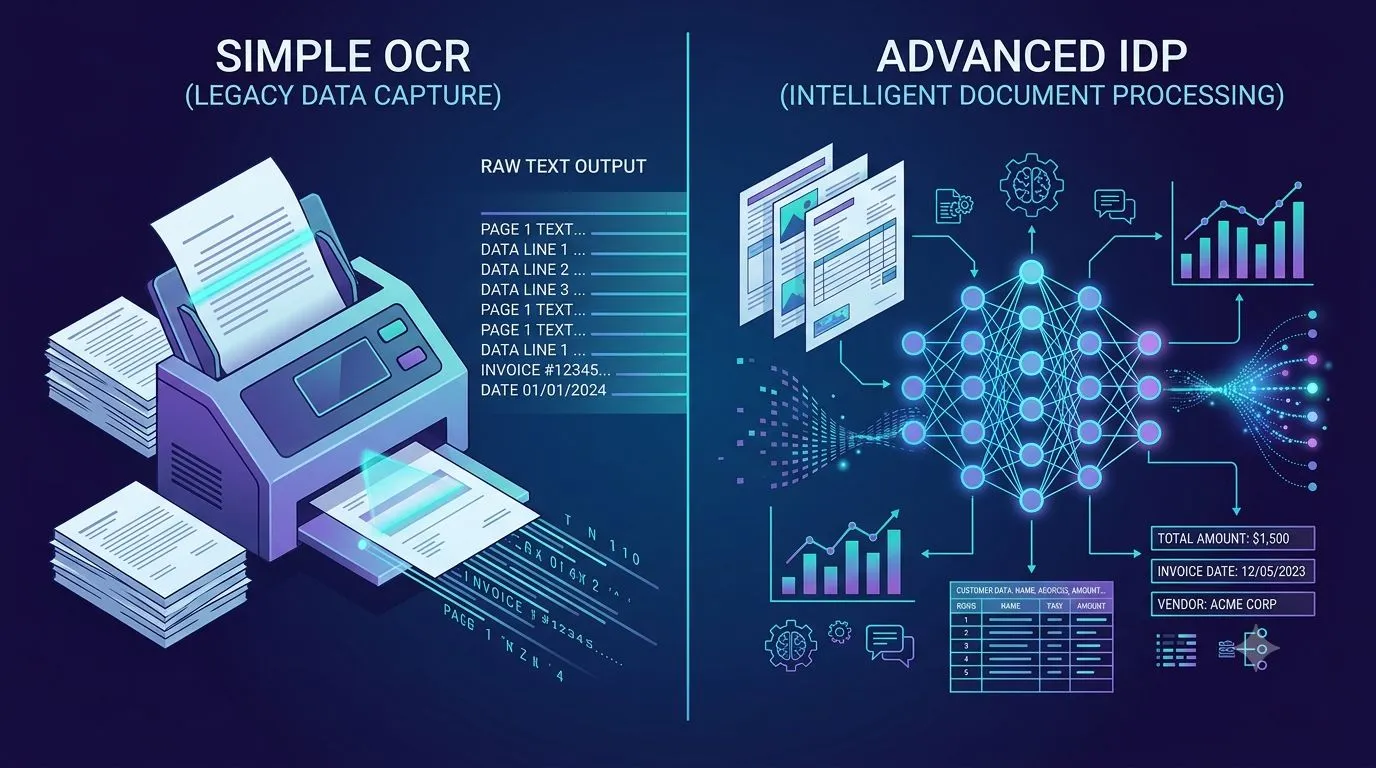
OCR has helped enterprises digitize scanned documents for decades, but recognizing text is only the beginning of a business document workflow. An invoice total can be read perfectly and still be assigned to the wrong field. A contract date can be captured accurately but interpreted incorrectly. A table can retain every number while losing the relationships between rows and columns.
These gaps create manual checks, correction queues, and downstream data errors that character recognition alone cannot address.
This article compares OCR and Intelligent Document Processing, or IDP, and explains why enterprises increasingly need document classification, contextual extraction, validation, exception handling, source evidence, and structured data rather than searchable text alone.
What Is OCR and What Does It Produce?
OCR, or optical character recognition, converts text contained in scanned pages, images, and photographed documents into machine-readable characters. Its primary function is recognition.
OCR Converts Images Into Machine-Readable Text
OCR identifies characters, words, and text regions in image-based documents. The output can then be searched, copied, indexed, or passed into another process.
OCR Accuracy Measures Character Recognition
OCR accuracy generally indicates whether letters, numbers, and symbols were read correctly. It does not confirm whether the resulting information was assigned to the correct business field.
Searchable Text Is Not Structured Enterprise Data
A searchable invoice may contain the supplier name, tax amount, payment terms, and total, but those values still need to be identified, associated with the correct fields, checked, and converted into a usable structure.
What Is Intelligent Document Processing?
Intelligent document processing extends document recognition into classification, contextual extraction, validation, review, and structured output.
IDP Combines Recognition, Classification, Extraction, and Validation
Instead of stopping once text is readable, IDP determines what document is being processed, identifies relevant information, checks extracted values, and manages uncertain cases.
IDP Identifies the Document Before Extraction
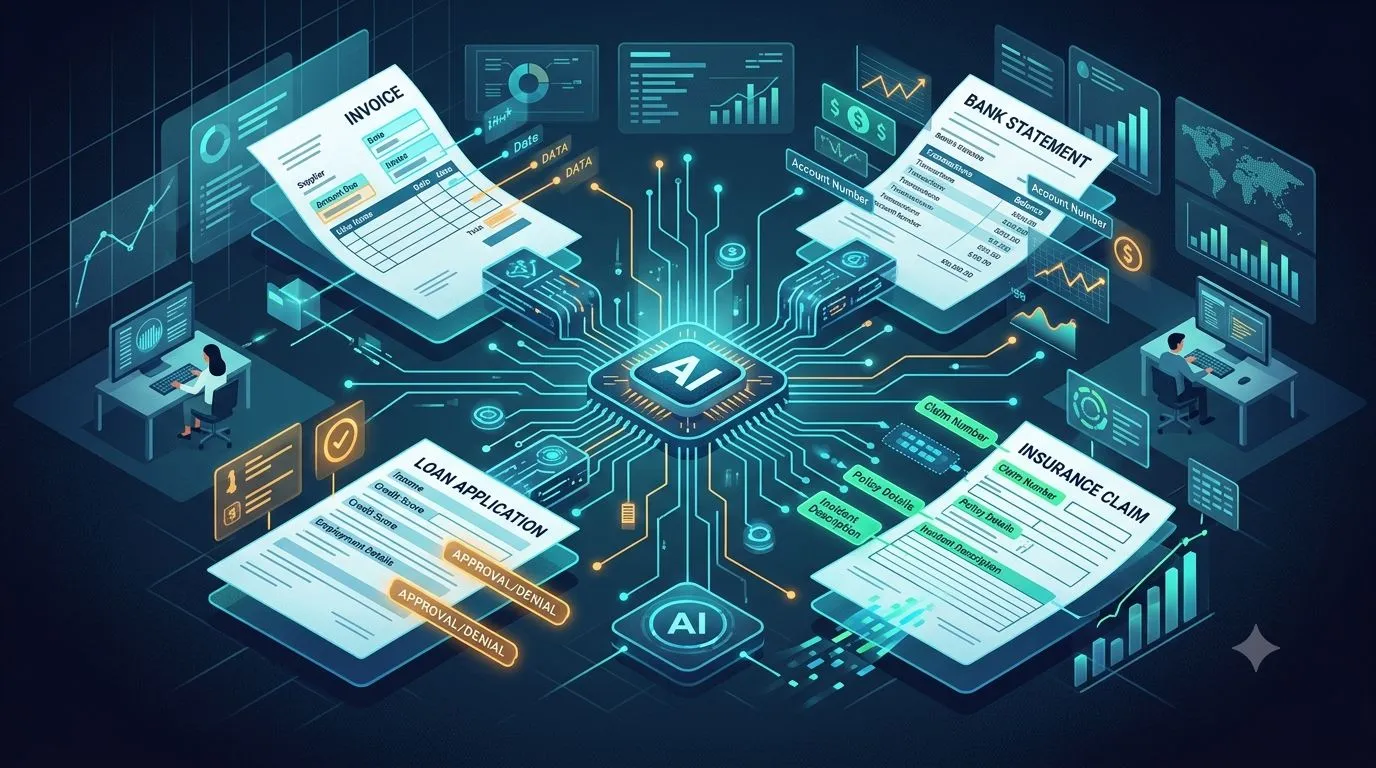
Knowing whether a file is an invoice, bank statement, insurance claim, loan application, or contract helps determine which fields, relationships, and validation conditions apply.
IDP Produces Structured Business Information
Information can be returned as defined fields, entities, tables, line items, and relationships rather than one block of machine-readable text.
IDP Connects Approved Data With Business Systems
Once data passes required checks, it can be prepared for ERP, CRM, accounting, lending, claims, and other enterprise applications.
OCR vs IDP: What Is the Core Difference?
The core difference is that OCR recognizes text, while IDP interprets, structures, validates, and routes document information.
A broader comparison of IDP, OCR, and RPA also shows how recognition, document intelligence, and process execution serve different parts of a business workflow.
OCR Reads Characters, IDP Interprets Context
OCR may read "Net 30" accurately. IDP can identify that phrase as a payment term and associate it with the relevant invoice or agreement.
OCR Produces Text, IDP Produces Structured Data
IDP can convert document content into defined fields such as supplier name, invoice date, tax amount, payment terms, and invoice total.
OCR Stops at Recognition
IDP continues through validation, confidence checks, exception handling, and review after information has been extracted.
OCR Focuses on the Page
IDP supports a wider document workflow that can include related pages, supporting documents, reference records, and receiving business systems.
Why Basic Text Extraction Is Not Enough
Enterprise processes require information that is usable, verifiable, and associated with the correct business context.
Correct Text Can Still Produce Incorrect Data
Reading "$92,000" correctly does not determine whether it represents revenue, debt, a claim amount, an invoice total, or a contract value.
A Value Needs Business Context
Entity, reporting period, document type, heading, table position, and surrounding language can all determine what a value means.
Enterprise Data Must Be Checked Before Use
Financial, operational, lending, and insurance processes often require extracted information to be tested against related fields, reference data, or supporting records.
OCR Leaves Classification and Verification Work
Employees may still need to determine document type, identify required fields, verify amounts, resolve conflicts, and enter information into other systems.
Text Extraction Does Not Decide What Happens Next
Recognition alone cannot determine whether a document should be accepted, rejected, reviewed, matched, approved, or sent into an exception process.
The Hidden OCR Problem: Right Text, Wrong Data
One of the most serious OCR limitations is that technically accurate recognition can still lead to an incorrect business record.
A Correct Number Can Map to the Wrong Field
A value may be captured correctly but assigned to subtotal rather than invoice total, or to current assets rather than another financial category.
A Correct Date Can Be Misclassified
The same document might contain an invoice date, due date, service period, approval date, and payment date. Recognition does not establish which one was captured.
Character Confidence Does Not Confirm Meaning
A system may be highly confident that it read "8.5%" correctly while remaining unable to determine whether the percentage represents tax, interest, discount, or ownership.
Correct Fields Can Still Lose Their Relationships
Supplier name, invoice total, PO number, and tax may all be accurate individually. If they are connected to different invoices within a combined file, the final record is still wrong.
Why Document Variation Exposes OCR Limits
Enterprise documents come from many suppliers, banks, customers, partners, and business units, so their formats rarely remain consistent.
Business Documents Use Different Layouts
The same information may appear at the top of one document, inside a table in another, and near the end of a third.
Small Format Changes Can Break Fixed Rules
A new logo, shifted column, extra address line, or redesigned header can move fields away from expected coordinates.
Unstructured Documents Rarely Use Fixed Positions
Contracts, financial reports, correspondence, claims files, and supporting documents often express information through paragraphs, sections, tables, and variable layouts.
More Variation Means More Maintenance
As document formats increase, template-based extraction can require more configuration changes and create more manual exceptions.
Why Tables and Structure Matter
Text alone cannot preserve all the meaning encoded in a document's layout.
Rows and Columns Carry Meaning
Financial statements, invoices, and bank statements depend on the relationship between headers, categories, periods, quantities, and values.
Reading Order Can Change Meaning
Multi-column pages can produce incorrect text sequences if separate sections are flattened into one reading order.
Merged Cells Can Break Relationships
Complex tables may contain merged headers, multi-line entries, and values that apply to several rows or periods.
Sections and Footnotes Provide Context
A figure in a footnote may qualify a number reported elsewhere. If that connection disappears during extraction, the resulting data may be incomplete.
Why Classification Comes Before Reliable Extraction
Reliable extraction depends on first understanding what type of document is being processed.
The Same Value Means Different Things Across Documents
"$10,000" could represent an invoice total, insurance claim, bank balance, loan amount, or contract obligation.
Mixed Files Need Logical Separation
A single uploaded PDF may contain an invoice, receipt, purchase order, and supporting correspondence. These should be separated before their data is combined.
Each Document Type Needs Different Fields
Invoices require supplier, PO, tax, and payment information, while bank statements require account details, periods, balances, and transaction rows.
Uncertain Classification Should Trigger Review
If the system cannot confidently identify a document type, review is safer than forcing the file into an incorrect category.
How IDP Adds Context
IDP extends recognition by preserving document structure and interpreting how extracted values relate to their surrounding information.
Context-Aware Extraction Connects Fields and Entities
Values can be associated with the correct labels, companies, customers, accounts, reporting periods, or transactions.
Layout Analysis Preserves Document Structure
Tables, sections, columns, headings, and spatial relationships can remain connected to extracted information.
Semantic Interpretation Recognizes Meaning Across Different Wording
Similar concepts can be identified even when different documents use different labels.
Cross-Page Context Connects Long Documents
A value on one page can be associated with qualifications, definitions, or supporting information appearing later in the file.
Cross-Document Context Links Related Records
Invoices can be connected with purchase orders and receipts, while claims, loans, and financial processes can bring together evidence from several related documents.
Why Validation Separates IDP From OCR
Extraction determines what information appears in a document. Validation determines whether that information is suitable for enterprise use.
Field Checks Confirm Basic Validity
Fields can be checked for presence, expected format, range, and data type before they proceed.
Cross-Field Checks Test Internal Relationships
Invoice totals can be compared with subtotals and taxes, while dates can be checked for logical order.
Cross-Document Checks Compare Related Records
An invoice can be checked against a purchase order and receipt, while claim or lending data can be compared across supporting documents.
Reference Checks Use Approved Enterprise Data
Supplier identities, account information, customer records, or other extracted values can be compared with approved internal records.
Business Rules Control What Proceeds
Defined rules determine whether data is accepted, rejected, or sent for review.
How IDP Handles Exceptions and Review
Enterprise document processing cannot assume every document will be processed automatically. Exceptions need a controlled path.
Confidence Scores Identify Uncertain Fields
Low-confidence fields can be isolated so reviewers inspect the specific values that need attention.
Business Impact Can Override Confidence
A high-confidence account number or large payment amount may still require review because an incorrect value could have significant consequences.
Conflicts Can Be Routed to the Right Reviewer
Disagreements between documents can be directed to employees with the relevant business knowledge.
People Can Focus on Exceptions
Instead of checking every document, reviewers can concentrate on uncertain, conflicting, or higher-impact cases.
Corrections Support Later Accuracy Analysis
Recording changes helps identify fields and document patterns that repeatedly create problems.
Why Source Traceability Matters
Enterprise users need to know where extracted information came from, particularly when data supports financial or operational decisions.
Values Should Remain Connected to Evidence
An extracted amount, date, clause, or identifier should retain a connection to the original source.
Source References Speed Up Verification
Page, section, table, and field references let reviewers locate supporting evidence without reading an entire document.
Evidence Separates Facts From AI Interpretation
Direct source content should remain distinguishable from conclusions produced through AI interpretation.
Processing History Supports Review
Correction and approval records show how extracted information changed before acceptance.
How IDP Connects With Enterprise Systems
The value of structured document information increases when verified data can move into the applications that depend on it.
Validated Data Can Map Into Business Applications
Structured output can correspond with fields in ERP, CRM, lending, claims, and accounting systems.
Failed Checks Can Stop Incorrect Data
Records that do not meet validation conditions can remain outside systems of record until resolved.
Status Information Can Travel With the Data
Receiving applications can retain whether a record was automatically accepted, corrected, reviewed, or approved.
Structured Output Reduces Re-Entry
Employees no longer need to repeatedly move information manually from source documents into business applications.
Where OCR Still Works Well
OCR remains useful where the business objective is primarily text recognition rather than contextual interpretation.
Paper Records for Search and Archiving
OCR can make scanned archives searchable without requiring structured field extraction.
Clean Printed Text
Documents with clear characters and consistent layouts are well suited to character recognition.
Low-Variation Documents
Stable formats with limited structured-data requirements may not require broader document processing.
Processes With Existing Human Verification
OCR can remain sufficient where employees already review the final output before it is used.
When Should an Enterprise Move Beyond OCR?
An enterprise should consider moving beyond OCR when recognition alone leaves substantial interpretation, checking, and data preparation work.
Document Layouts Change Frequently
Frequent format variation makes fixed extraction rules harder to maintain.
Manual Classification Remains Necessary
Employees should not have to identify every incoming document before extraction can begin.
Tables and Multi-Page Relationships Matter
Structured relationships need to remain intact when documents contain financial tables, schedules, or information spread across pages.
Values Require Business Context
Knowing what was read is insufficient if employees must still determine what the value represents.
Related Records Must Be Compared
Processes such as invoice matching, lending, claims, and financial analysis often require cross-document checks.
Manual Verification Remains High
Persistent checking indicates that recognition has not solved the wider document processing problem.
Downstream Systems Need Defined Data
If business applications require specific structured fields, raw OCR text creates another processing stage.
Enterprise Use Cases Where IDP Goes Beyond OCR
The difference becomes clearer in processes where documents affect financial or operational decisions.
Accounts Payable
AP processing may require invoice classification, line-item extraction, purchase order matching, validation, duplicate checks, and exception handling.
Financial Operations
Bank statements and financial reports require preserved transaction, table, account, period, and balance relationships.
Insurance Claims
Claim decisions can depend on policy records, forms, invoices, evidence, and supporting documents considered together.
Lending
Borrower information may need to be connected across applications, bank statements, financial reports, identification documents, and other records.
Contract Processing
Clauses, obligations, rates, dates, and renewal terms often need interpretation based on surrounding language and related sections.
How Should Enterprises Compare OCR and IDP?
Enterprises should compare OCR and IDP based on the quality and usability of final business data rather than recognition accuracy alone.
Measure Business Data Accuracy
Evaluation should confirm whether the correct value was assigned to the correct field, entity, period, and document.
Measure Remaining Manual Review
A system that reads text accurately but still requires extensive human checking may provide limited operational value.
Test Real Document Variation
Evaluation sets should include actual supplier, customer, bank, contract, and partner formats rather than clean samples alone.
Measure Structural Accuracy
Tables, line items, reading order, and cross-page relationships should remain correct after processing.
Track Validation Errors
Measure both rejected correct values and incorrect values that pass through without being detected.
Measure Traceability and Data Readiness
Check whether extracted values remain linked to source evidence and arrive in a structure that receiving applications can use.
Compare Cost With Remaining Manual Work
Processing cost should be considered alongside review, correction, template maintenance, and manual data-entry effort.
From Text Recognition to Business-Ready Data
OCR and IDP should not be viewed simply as two competing technologies. They address different stages of document processing.
OCR Establishes What Text Appears
Character recognition creates the machine-readable foundation for image-based documents.
Classification Establishes the Document Type
Knowing what is being processed determines which information should be extracted.
Contextual Extraction Establishes Meaning
Fields, entities, relationships, tables, and surrounding content provide the business interpretation.
Validation Establishes Whether Data Can Be Used
Checks against internal relationships, related records, and approved data determine whether information can proceed.
Human Review Resolves Exceptions
People handle cases where evidence is uncertain, conflicting, or financially significant.
Integration Makes Approved Data Available
Validated structured information can then enter the enterprise applications that require it.
Conclusion: OCR Reads Documents, but Enterprises Need Usable Data
OCR continues to play an important role in digitizing paper and image-based documents. Its limitation is not that it cannot read text. The limitation appears when enterprises expect recognized text to become trustworthy business data automatically.
Enterprise workflows require document classification, preserved structure, contextual extraction, validation, exception handling, source evidence, and structured output. IDP adds these stages around recognition so information can be interpreted and checked before reaching business systems.
The practical question is therefore no longer whether software can read a page. It is whether the resulting information can be understood, verified, traced to its source, and used safely in the process that follows.
For organizations processing varied, high-volume, or data-sensitive documents, intelligent document processing software can provide the additional classification, contextual extraction, validation, review, and structured-data capabilities required beyond basic OCR.





















Sign in to leave a comment.